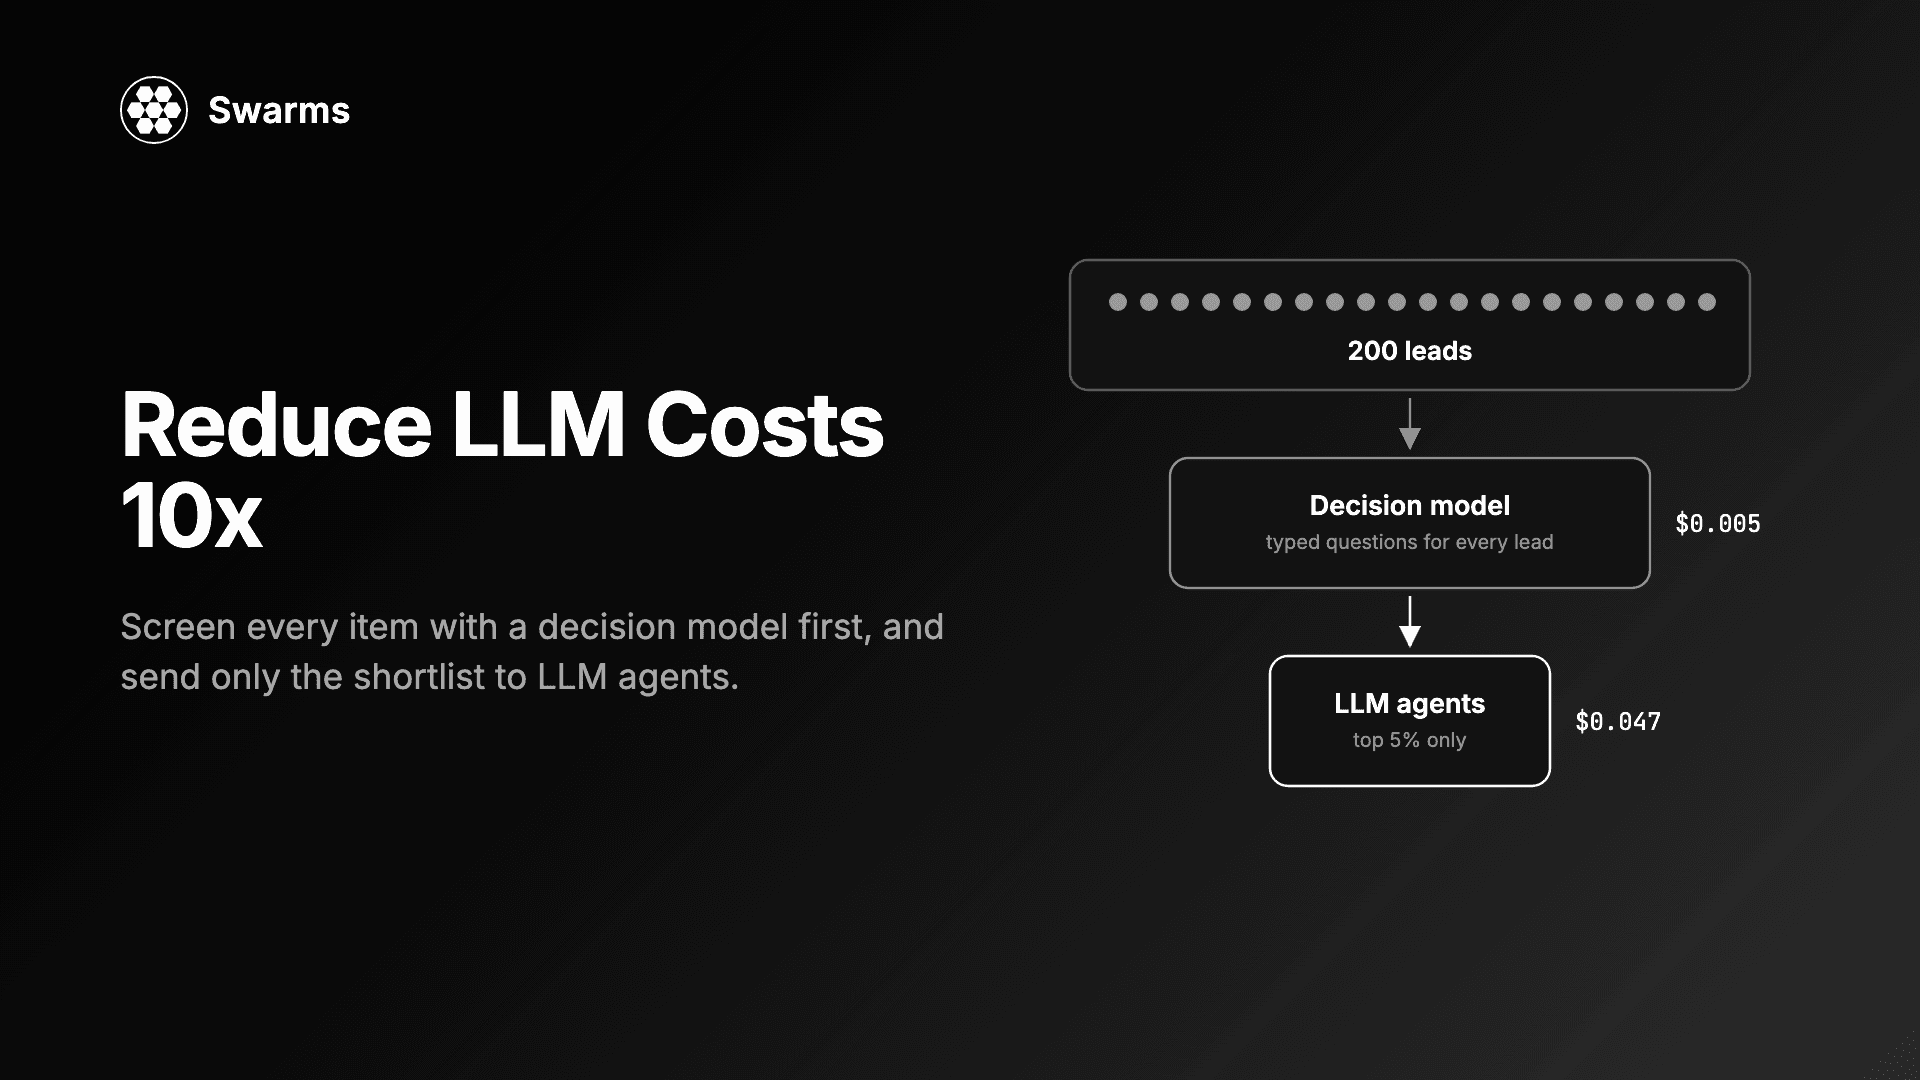
The fastest way to reduce LLM costs in a high-volume pipeline is to stop sending every item to an LLM. Most pipelines that triage leads, tickets, documents or applications spend the bulk of their tokens on the screening step: reading every item to decide whether it deserves real work. That step is a set of typed questions, not a writing task. In this guide you will move it to a decision model, Swarms' DecisionModel, which answers typed questions about each item in one cheap request, and keep LLM agents for the few items that pass. On our measured run, screening with the decision model cost 10.1x less per item than the cheapest LLM screener we could write, and answered about 3x faster.
Every number in this post comes from running the code below against Swarms 16 on October 3, 2026. Where a number is extrapolated from a measured sample, the post says so.
The screening funnel pattern
The pattern has four stages, and only the last one uses an LLM:
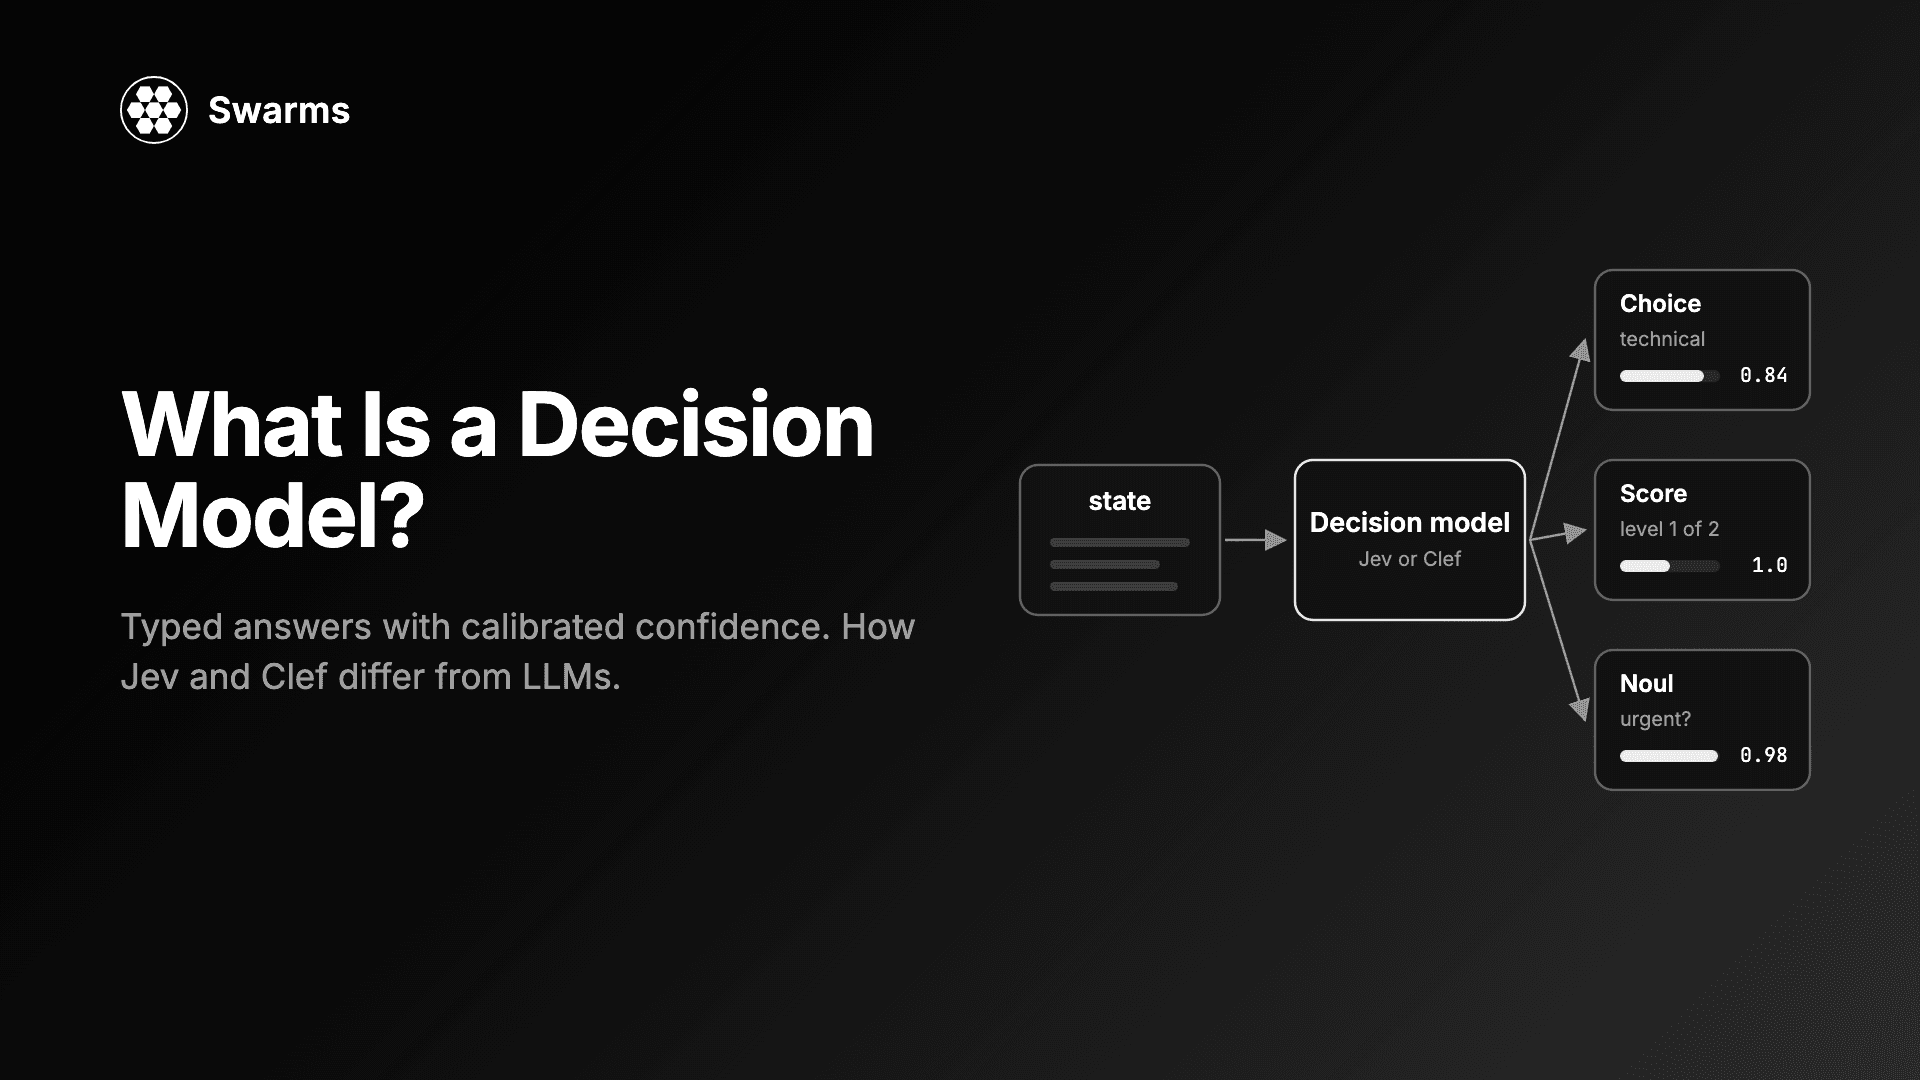
- Ask typed questions about every item. A decision model answers Choice (pick one option), Score (rate on ordered levels) and Noul (probability a statement is true) questions about one item in one request, with calibrated probabilities instead of prose.
- Combine the answers in code. Weights, hard gates and thresholds live in your Python, where you can read, test and change them without re-prompting anything.
- Keep the top few percent. Sort by the combined score and cut.
- Send the shortlist to LLM agents for deep work. Research, drafting, multi-step reasoning: the work LLMs are actually good at, on the items that justify it.
The reason this cuts cost is in the price tables. TypeSafe's jev-latest, the default DecisionModel, is listed in Swarms' built-in price table at $0.042 per million input tokens and $0 for output. gpt-5.4-mini is $0.75 per million input and $4.50 per million output in litellm's price table. A decision model is not a smaller LLM; it is a different kind of model that returns numbers, so you pay for reading the item and nothing for writing. If you want the background on what a decision model is and how it differs from an LLM classifier, read What Is a Decision Model?. This post is about using one to cut a bill.
The example below screens inbound sales leads for a data-pipeline monitoring product. The same shape fits support tickets, content moderation queues, document intake and research triage. The repository ships a longer version that screens 500 synthetic resumes in examples/decision_models/decision_screening_funnel.py.
Install
pip install -U swarms
# or
uv pip install -U swarms
The examples need two keys: an OpenAI key for the LLM agents, and a TypeSafe key for the decision model.
export OPENAI_API_KEY="sk-..."
export TYPESAFE_API_KEY="..."
Or put both in a .env file in your working directory; Swarms loads it automatically on import. Then check your version:
python -c "import swarms; print(swarms.__version__)"
DecisionModel needs Swarms 16 or later. Its price table and per-request cost (calculate_cost, added in #2431) ship in 16.0.1 on PyPI.
Step 1: One request, three typed answers
Before building the funnel, see what a decision model returns. Create first_call.py:
from swarms import DecisionModel

# Reads TYPESAFE_API_KEY and calls TypeSafe's jev-latest by default.
model = DecisionModel()

result = model.run(
    state={
        "ideal_customer": "Data teams at companies with 200 to 5,000 employees",
        "lead": {
            "employees": 900,
            "contact_role": "Head of Data Platform",
            "message": "Our dbt models broke three times last month. Can we see a demo next week?",
        },
    },
    questions={
        "request": {
            "type": "choice",
            "instructions": "What is the `lead` asking for?",
            "criteria": {
                "evaluation": "A demo, a trial, pricing or a vendor evaluation",
                "question": "A product or technical question",
                "other": "Anything else",
            },
        },
        "fit": {
            "type": "score",
            "instructions": "How well does the `lead` match the `ideal_customer`?",
            "criteria": ["Not a fit", "Partial fit", "Strong fit"],
        },
        "decision_maker": {
            "type": "noul",
            "instructions": "The contact leads or manages a data team.",
        },
    },
)

answers = result["answers"]
print(answers["request"]["choice"], answers["request"]["confidence"])
print(answers["fit"]["score"], answers["fit"]["probabilities"])
print(answers["decision_maker"]["noul"])
print(result["usage"], model.calculate_cost(result["usage"])["total_cost"])
What we got:
evaluation 1.0
1.99 {'0': 0.0, '1': 0.01, '2': 0.99}
0.94
{'input_tokens': 476, 'output_tokens': 70} 1.9992e-05
Three questions, one request, two thousandths of a cent. The Choice answer comes with a confidence, the Noul answer is a probability, and the Score is a float: 1.99 is the probability-weighted level, which is what makes scores sortable without ties. calculate_cost(result["usage"]) prices one response; called with no argument it prices every request the model has made, which is what the funnel uses. The token and cost tracking guide covers the same accounting for agents and swarms.
Step 2: Define the screen
The screen is data: an ideal customer profile, four questions, and weights. Keeping it in its own module means the funnel and the measurement script screen with exactly the same questions. Create leads.py:
import random

IDEAL_CUSTOMER = {
    "product": "Monitoring and alerting for data pipelines (Airflow, dbt, Spark)",
    "best_fit": [
        "Company with 200 to 5,000 employees",
        "Runs its own data pipelines in production",
        "Contact leads or manages a data or platform team",
        "Based in North America or Europe",
    ],
}

QUESTIONS = {
    "request": {
        "type": "choice",
        "instructions": "What is the `lead` asking for?",
        "criteria": {
            "evaluation": "A demo, a trial, pricing or a vendor evaluation",
            "question": "A product or technical question",
            "pitch": "Selling us a service, or looking for a job",
            "other": "Students, unsubscribes, spam and anything else",
        },
    },
    "fit": {
        "type": "score",
        "instructions": "How well does the company in the `lead` match the `ideal_customer`?",
        "criteria": [
            "Not a fit",
            "Weak fit",
            "Partial fit",
            "Strong fit",
            "Ideal customer",
        ],
    },
    "intent": {
        "type": "noul",
        "instructions": "The `lead` describes a concrete pipeline problem or a buying timeline.",
    },
    "decision_maker": {
        "type": "noul",
        "instructions": "The contact in the `lead` leads or manages a data or platform team.",
    },
}

WEIGHTS = {"fit": 0.45, "intent": 0.30, "decision_maker": 0.25}

MESSAGES = [
    ("We run about 400 Airflow DAGs and silent failures keep reaching our dashboards. We want a tool in place this quarter.", 3),
    ("Our dbt models broke three times last month before anyone noticed. Can we see a demo next week?", 3),
    ("We are evaluating pipeline monitoring vendors for a Q3 rollout across 12 Spark jobs. What does pricing look like at our size?", 3),
    ("How do you compare to the alerting we already get from Datadog?", 8),
    ("Do you support Dagster, or only Airflow?", 8),
    ("Saw your talk at a meetup. Interested, but no timeline yet.", 8),
    ("I'm a student writing a thesis on data quality. Is there a free license?", 10),
    ("We are an SEO agency and can get your site to page one of Google.", 12),
    ("Are you hiring data engineers? My resume is attached.", 10),
    ("Please remove me from your mailing list.", 10),
    ("Just browsing.", 12),
]
ROLES = [
    "VP of Data",
    "Head of Data Platform",
    "Data Engineering Manager",
    "Senior Data Engineer",
    "Analytics Engineer",
    "Founder",
    "Marketing Coordinator",
    "Recruiter",
    "Student",
]
INDUSTRIES = [
    "Fintech",
    "E-commerce",
    "Healthcare",
    "Logistics",
    "Media",
    "SaaS",
    "Marketing agency",
    "University",
]
COUNTRIES = [
    "United States",
    "Germany",
    "United Kingdom",
    "Canada",
    "Netherlands",
    "Brazil",
    "India",
    "Australia",
]
EMPLOYEES = [8, 25, 60, 150, 400, 900, 2500, 8000, 30000]


def make_leads(count: int, seed: int = 7) -> list:
    """
    Generate synthetic inbound leads, most of them poor fits.

    Args:
        count: Number of leads.
        seed: Random seed, so every run screens the same pool.

    Returns:
        Lead dictionaries.
    """
    rng = random.Random(seed)
    messages, weights = zip(*MESSAGES)
    return [
        {
            "id": f"L{index:04d}",
            "company_industry": rng.choice(INDUSTRIES),
            "employees": rng.choice(EMPLOYEES),
            "country": rng.choice(COUNTRIES),
            "contact_role": rng.choice(ROLES),
            "message": rng.choices(messages, weights)[0],
        }
        for index in range(count)
    ]


def lead_score(answers: dict) -> float:
    """
    Combine the decision model's answers into one score.

    Args:
        answers: Answers keyed by question id.

    Returns:
        A score from 0 to 1, or 0 when the lead is not a buyer.
    """
    if answers["request"]["choice"] in ("pitch", "other"):
        return 0.0
    fit_levels = len(QUESTIONS["fit"]["criteria"]) - 1
    values = {
        "fit": answers["fit"]["score"] / fit_levels,
        "intent": answers["intent"]["noul"],
        "decision_maker": answers["decision_maker"]["noul"],
    }
    return sum(WEIGHTS[key] * values[key] for key in WEIGHTS)
Three decisions in this file are worth copying.
The questions are specific and checkable. "The contact leads or manages a data or platform team" is a statement the model can verify against the item. "Is this a good lead?" is not; it hides the criteria, so you cannot tune them later.
The gate is code, not a question weight. A vendor pitch with a perfect company profile should score zero, not 0.7. lead_score returns 0 when the Choice answer is pitch or other, and only then applies the weights.
The weights are yours. Fit counts for 45%, intent 30%, seniority 25%. If sales tells you intent matters more than company size, you change one number and re-run. No prompt changes, no re-validation of output parsing.
make_leads generates a synthetic pool with a fixed seed, so every run screens the same 200 leads; roughly one in seven has a strong buying message, and far fewer combine that with the right company and contact.
Step 3: Screen everything, reason about the shortlist
Now the funnel itself. The decision model screens all 200 leads, 20 requests at a time, and gpt-5.4 agents write an account brief and a first reply for the top 5%. Create screen.py:
import asyncio
import json
import math
import time

import litellm

from swarms import Agent, DecisionModel, run_agents_with_different_tasks

from leads import IDEAL_CUSTOMER, QUESTIONS, lead_score, make_leads

NUM_LEADS = 200
SHORTLIST_SHARE = 0.05
DEEP_WORK_MODEL = "gpt-5.4"


async def screen_all(model: DecisionModel, leads: list) -> list:
    """
    Screen every lead with the decision model, 20 requests at a time.

    Args:
        model: Decision model that answers the screening questions.
        leads: Leads to screen.

    Returns:
        One result per lead with its score and latency.
    """
    limit = asyncio.Semaphore(20)

    async def screen(lead: dict) -> dict:
        async with limit:
            started = time.perf_counter()
            response = await model.arun(
                state={"ideal_customer": IDEAL_CUSTOMER, "lead": lead},
                questions=QUESTIONS,
            )
            return {
                "lead": lead,
                "score": lead_score(response["answers"]),
                "seconds": time.perf_counter() - started,
            }

    return await asyncio.gather(*(screen(lead) for lead in leads))


def llm_cost(model_name: str, usage: dict) -> float:
    """
    Price an agent's token usage with litellm's price table.

    Args:
        model_name: Model the agent ran on.
        usage: The agent's usage dictionary.

    Returns:
        Cost in US dollars.
    """
    prompt_cost, completion_cost = litellm.cost_per_token(
        model=model_name,
        prompt_tokens=usage["input_tokens"],
        completion_tokens=usage["output_tokens"],
    )
    return prompt_cost + completion_cost


leads = make_leads(NUM_LEADS)
model = DecisionModel()

started = time.perf_counter()
screened = asyncio.run(screen_all(model, leads))
screen_wall = time.perf_counter() - started
screen_cost = model.calculate_cost()

shortlist_size = math.ceil(NUM_LEADS * SHORTLIST_SHARE)
shortlist = sorted(screened, key=lambda r: r["score"], reverse=True)[
    :shortlist_size
]

print(f"Screened {NUM_LEADS} leads in {screen_wall:.1f} s")
print(
    f"  {screen_cost['input_tokens']} input tokens, "
    f"${screen_cost['total_cost']:.5f} total, "
    f"${screen_cost['total_cost'] / NUM_LEADS:.7f} per lead"
)
print(
    f"  {sum(r['seconds'] for r in screened) / NUM_LEADS:.2f} s per request"
)
print(f"\nTop 5 of the {shortlist_size}-lead shortlist:")
for result in shortlist[:5]:
    lead = result["lead"]
    print(
        f"  {result['score']:.2f}  {lead['contact_role']}, "
        f"{lead['employees']} employees, {lead['country']}: "
        f"{lead['message'][:50]}..."
    )

writers = [
    Agent(
        agent_name=f"Account-Executive-{r['lead']['id']}",
        system_prompt=(
            "You are an account executive. For the lead you are given, write "
            "a three-bullet account brief (why they fit, what to ask, what "
            "could block the deal), then a short first reply that refers to "
            "their message."
        ),
        model_name=DEEP_WORK_MODEL,
        max_loops=1,
        output_type="final",
        print_on=False,
    )
    for r in shortlist
]
started = time.perf_counter()
briefs = run_agents_with_different_tasks(
    [
        (
            writer,
            f"Ideal customer: {json.dumps(IDEAL_CUSTOMER)}\n\n"
            f"Lead: {json.dumps(r['lead'])}",
        )
        for writer, r in zip(writers, shortlist)
    ]
)
deep_wall = time.perf_counter() - started
deep_cost = sum(llm_cost(DEEP_WORK_MODEL, w.usage) for w in writers)

print(
    f"\nDeep work on {shortlist_size} leads with {DEEP_WORK_MODEL}: "
    f"{deep_wall:.1f} s, ${deep_cost:.4f}, "
    f"${deep_cost / shortlist_size:.4f} per lead"
)
print(
    f"Pipeline total: ${screen_cost['total_cost'] + deep_cost:.4f} "
    f"for {NUM_LEADS} leads"
)
print(f"\nBrief for {shortlist[0]['lead']['id']}:\n\n{briefs[0]}")
Our run (the brief is cut after its first bullet):
Screened 200 leads in 5.3 s
  127791 input tokens, $0.00537 total, $0.0000268 per lead
  0.46 s per request

Top 5 of the 10-lead shortlist:
  0.98  VP of Data, 400 employees, United States: We run about 400 Airflow DAGs and silent failures ...
  0.98  VP of Data, 2500 employees, United Kingdom: We are evaluating pipeline monitoring vendors for ...
  0.95  Data Engineering Manager, 2500 employees, United States: We run about 400 Airflow DAGs and silent failures ...
  0.88  Senior Data Engineer, 400 employees, Germany: Our dbt models broke three times last month before...
  0.88  Senior Data Engineer, 900 employees, Germany: We are evaluating pipeline monitoring vendors for ...

Deep work on 10 leads with gpt-5.4: 6.4 s, $0.0473, $0.0047 per lead
Pipeline total: $0.0527 for 200 leads

Brief for L0082:

- **Why they fit:** Strong ICP match: 400 employees, US-based fintech, and the contact is a **VP of Data**. They run a meaningful production footprint with **~400 Airflow DAGs**, and the pain is exactly what we solve: **silent pipeline failures reaching dashboards**.
The shortlist is what a sales lead would pick by hand: concrete pipeline pain, a buying timeline, a data leader, a company in range. All 200 leads cost half a cent to screen. A few implementation details matter:
- One request per item, all questions at once. Four questions cost one round trip, not four. That is why the per-lead price stays flat as you add questions; you pay for the extra question text as input tokens, nothing more.
arun with a semaphore. DecisionModel.arun is the async version of run. The semaphore caps concurrency at 20, and the client retries rate limits and overloads (408, 429, 500, 502, 503, 504, 529) with backoff that honours retry-after.- A fresh, single-turn agent per shortlisted lead.
output_type="final" returns just the answer, print_on=False keeps panels out of your logs, and separate agents keep one lead's context out of another's. run_agents_with_different_tasks runs them concurrently.
- Cost from usage, not guesswork.
model.calculate_cost() sums the provider's reported token counts over all 200 requests; each agent's usage is priced with litellm's table.
Step 4: Measure the LLM screener on the same leads
A cost multiplier is only as honest as its baseline. The fair comparison is not "decision model vs. an agent writing essays"; it is a decision model against the cheapest LLM screener you would actually ship: gpt-5.4-mini, a short system prompt, the same four questions, JSON only. We also measured the variant teams often end up with, where the screener adds a one-sentence reason per answer. Create compare.py:
import json
import random
import time

import litellm

from swarms import Agent, DecisionModel

from leads import IDEAL_CUSTOMER, QUESTIONS, make_leads

SAMPLE_SIZE = 3
SCREEN_MODEL = "gpt-5.4-mini"

JSON_PROMPT = (
    "You screen inbound sales leads against an ideal customer profile. "
    "Reply with JSON only: "
    '{"request": "evaluation" | "question" | "pitch" | "other", '
    '"fit": 0-4 (0 not a fit, 4 ideal customer), '
    '"intent": 0-1 (the lead describes a concrete pipeline problem or buying timeline), '
    '"decision_maker": 0-1 (the contact leads or manages a data or platform team)}'
)
SCREENERS = {
    "LLM, JSON only": JSON_PROMPT,
    "LLM, JSON with reasons": JSON_PROMPT
    + ' Add a "reasons" field with one sentence per answer.',
}

sample = random.Random(1).sample(make_leads(200), SAMPLE_SIZE)
results = {}

model = DecisionModel()
seconds = []
for lead in sample:
    started = time.perf_counter()
    model.run(
        state={"ideal_customer": IDEAL_CUSTOMER, "lead": lead},
        questions=QUESTIONS,
    )
    seconds.append(time.perf_counter() - started)
results[f"Decision model ({model.model_name})"] = (
    model.calculate_cost()["total_cost"],
    sum(seconds),
)

for name, system_prompt in SCREENERS.items():
    cost, seconds = 0.0, 0.0
    for lead in sample:
        # A fresh agent per lead keeps earlier leads out of the context.
        screener = Agent(
            agent_name="Screener",
            system_prompt=system_prompt,
            model_name=SCREEN_MODEL,
            max_loops=1,
            output_type="final",
            print_on=False,
        )
        started = time.perf_counter()
        screener.run(
            f"Ideal customer: {json.dumps(IDEAL_CUSTOMER)}\n\n"
            f"Lead: {json.dumps(lead)}"
        )
        seconds += time.perf_counter() - started
        prompt_cost, completion_cost = litellm.cost_per_token(
            model=SCREEN_MODEL,
            prompt_tokens=screener.usage["input_tokens"],
            completion_tokens=screener.usage["output_tokens"],
        )
        cost += prompt_cost + completion_cost
    results[f"{name} ({SCREEN_MODEL})"] = (cost, seconds)

baseline_cost = results[f"Decision model ({model.model_name})"][0]
print(f"Per lead, measured on {SAMPLE_SIZE} leads:")
for name, (cost, seconds) in results.items():
    per_lead = cost / SAMPLE_SIZE
    print(
        f"  {name:<40} ${per_lead:.7f}  {seconds / SAMPLE_SIZE:.2f} s  "
        f"{cost / baseline_cost:5.1f}x cost  "
        f"${per_lead * 100_000:,.2f} per 100k leads"
    )
Our run:
Per lead, measured on 3 leads:
  Decision model (jev-latest)              $0.0000269  0.20 s    1.0x cost  $2.69 per 100k leads
  LLM, JSON only (gpt-5.4-mini)            $0.0002710  0.66 s   10.1x cost  $27.10 per 100k leads
  LLM, JSON with reasons (gpt-5.4-mini)    $0.0006168  0.91 s   22.9x cost  $61.67 per 100k leads
Three leads is a small sample, chosen to keep the test cheap; raise SAMPLE_SIZE for a tighter estimate. Two things suggest the numbers are stable. The decision model's per-lead cost on the sample ($0.0000269) matches the 200-lead run ($0.0000268), and the LLM screener's input is a fixed prompt plus one short lead, with JSON output of near-constant length. The latencies are sequential, one request at a time; the 0.46 s per request in Step 3 is the decision model under 20-way concurrency.
The multiplier comes from output. The JSON-only screener's answer is a few dozen tokens, but output tokens on gpt-5.4-mini cost six times its input tokens, and input already costs about 18 times the decision model's. Ask the screener to explain itself and the gap more than doubles, to 22.9x.
How far a decision model reduces LLM costs: measured vs. extrapolated
Here is the whole pipeline at the size we ran it, and extrapolated to 100,000 leads. Measured figures come from the runs above. Extrapolated figures multiply a measured per-item cost by an item count.
| Pipeline | 200 leads | 100,000 leads (extrapolated) |
|---|
Decision model screens all, gpt-5.4 agents work the top 5% | $0.0527 (measured) | $2.69 + $23.65 = $26.34 |
gpt-5.4-mini screens all (JSON), agents work the top 5% | $0.0542 (extrapolated) + $0.0473 (measured) = $0.1015 | $27.10 + $23.65 = $50.75 |
No screen: gpt-5.4 agents work every lead | $0.95 (extrapolated from 10) | $473 |
Read the table in three directions.
Screening alone: 10.1x cheaper. That is the stage the decision model replaces, and the multiplier in this post's title. Against a screener that writes reasons, 22.9x.
The whole funnel: about 18x cheaper than no funnel. Sending every lead to the gpt-5.4 agent would cost $0.95 for 200 leads; the funnel cost $0.0527. Most of that saving comes from the cut to 5%, and the decision model is what makes the cut nearly free: the screen is 10% of the funnel's bill.
Once screening is cheap, deep work is the bill. In our run the 10 agent calls cost $0.0473 and the 200 screening requests cost $0.0054. Your next lever for LLM cost optimization is no longer the screen, it is SHORTLIST_SHARE: every point you cut from the shortlist share saves more than the entire screening stage.
Time follows the same shape. The decision model answered in 0.20 s per lead sequentially against 0.66 s for the gpt-5.4-mini screener, and screened all 200 leads in 5.3 s of wall time.
Our live testing for this post, including every run above, cost about $0.06.
When the screening funnel is a bad fit
The pattern assumes many items, a small share worth deep work, and questions you can write down. When any of those fail, so does the case for it.
- Low volume. At 1,000 items a month the JSON-only LLM screener would cost about $0.27 (extrapolated from our per-lead figure). A second provider and key is not worth saving a quarter.
- Most items pass. If half your items need deep work, the agents dominate the bill and the screen's savings round to nothing. The funnel pays off when the shortlist is a few percent.
- The criteria are code. Employee count ranges, country lists and date windows belong in an
if statement, which is free and exact. Use the decision model for judgments that need reading: intent, tone, relevance, seniority from a title.
- The decision needs outside knowledge or several steps. A decision model answers about the state you give it. If deciding requires a search, a tool call or a chain of reasoning, that item needs an agent.
- You need a written reason for every item. The decision model returns probabilities, not explanations. If an audit trail of prose is a requirement, you are paying for the 22.9x row.
- A missed item is expensive, or the decision is about people. A top-5% cut silently drops 95% of items. For hiring, credit, medical or legal screens, treat the score as a ranking for human review, sample the rejected pile regularly, and check what your jurisdiction requires of automated decisions. Multi-agent system failure modes covers what goes wrong when one stage's silent errors feed the next.
We also did not measure screening accuracy against labeled data here; the shortlist above is a sanity check, not an evaluation. Before you switch a production screen, run both screeners on a few hundred items you have already labeled and compare what each one shortlists.
Where to go next
The funnel is one shape in a larger family; agent orchestration patterns covers the others, and a decision model can sit inside most of them as a router or a judge. The full list of what shipped with DecisionModel, including Cloudflare's Clef as a drop-in provider and the other examples in examples/decision_models/, is in the Swarms v16 "Overclock" release notes.
FAQ
How do I reduce LLM costs without losing quality?
Find the step where an LLM reads every item only to make a decision, and replace it with a decision model that answers the same questions as typed values. Keep the LLM for the items that pass. Then check quality directly: run both screeners on labeled items and compare their shortlists before switching.
How much does a decision model cost per request?
jev-latest is priced at $0.042 per million input tokens and $0 for output in Swarms' built-in price table. Our leads, with four questions, averaged about 640 input tokens and $0.0000268 per request. DecisionModel.calculate_cost() returns the exact figure from the provider's reported usage.
What is the difference between a decision model and an LLM classifier?
An LLM classifier generates text that you parse into a label. A decision model returns the label directly, with probabilities and a confidence, and charges nothing for output. What Is a Decision Model? explains the difference in depth.
Can I use Cloudflare instead of TypeSafe?
Yes. DecisionModel(model_name="clef") or model_name="clef-flash" routes to Cloudflare Workers AI and needs CLOUDFLARE_ACCOUNT_ID and CLOUDFLARE_AUTH_TOKEN. The built-in prices are $0.24 and $0.09 per million input tokens. We did not run Clef for this post, so the measurements above apply to jev-latest only.
Is cheap AI classification accurate enough for production?
It depends on your questions and your data, and no published benchmark can answer that for you. Specific, checkable questions help more than anything else. Measure on your own labeled items, keep a confidence threshold that routes unsure answers to a human or an agent, and audit a sample of what the screen rejects.
Have questions or feedback? Join our Discord community or check out the documentation.