A single LLM call commits to its first idea. If step one is wrong, every later step builds on the mistake and nothing goes back to check. Tree of Thoughts (ToT) replaces that one pass with a search: the model proposes several candidate next steps, rates them, drops the weak ones, and keeps going from the best. This guide shows how to run tree of thoughts in Python with the TreeOfThoughts agent that shipped in Swarms v16, starting with the Game of 24 from the original paper. Every number below came from a run we made with gpt-5.4-mini, including the runs where ToT got the answer wrong.
Tree of thoughts vs chain of thought
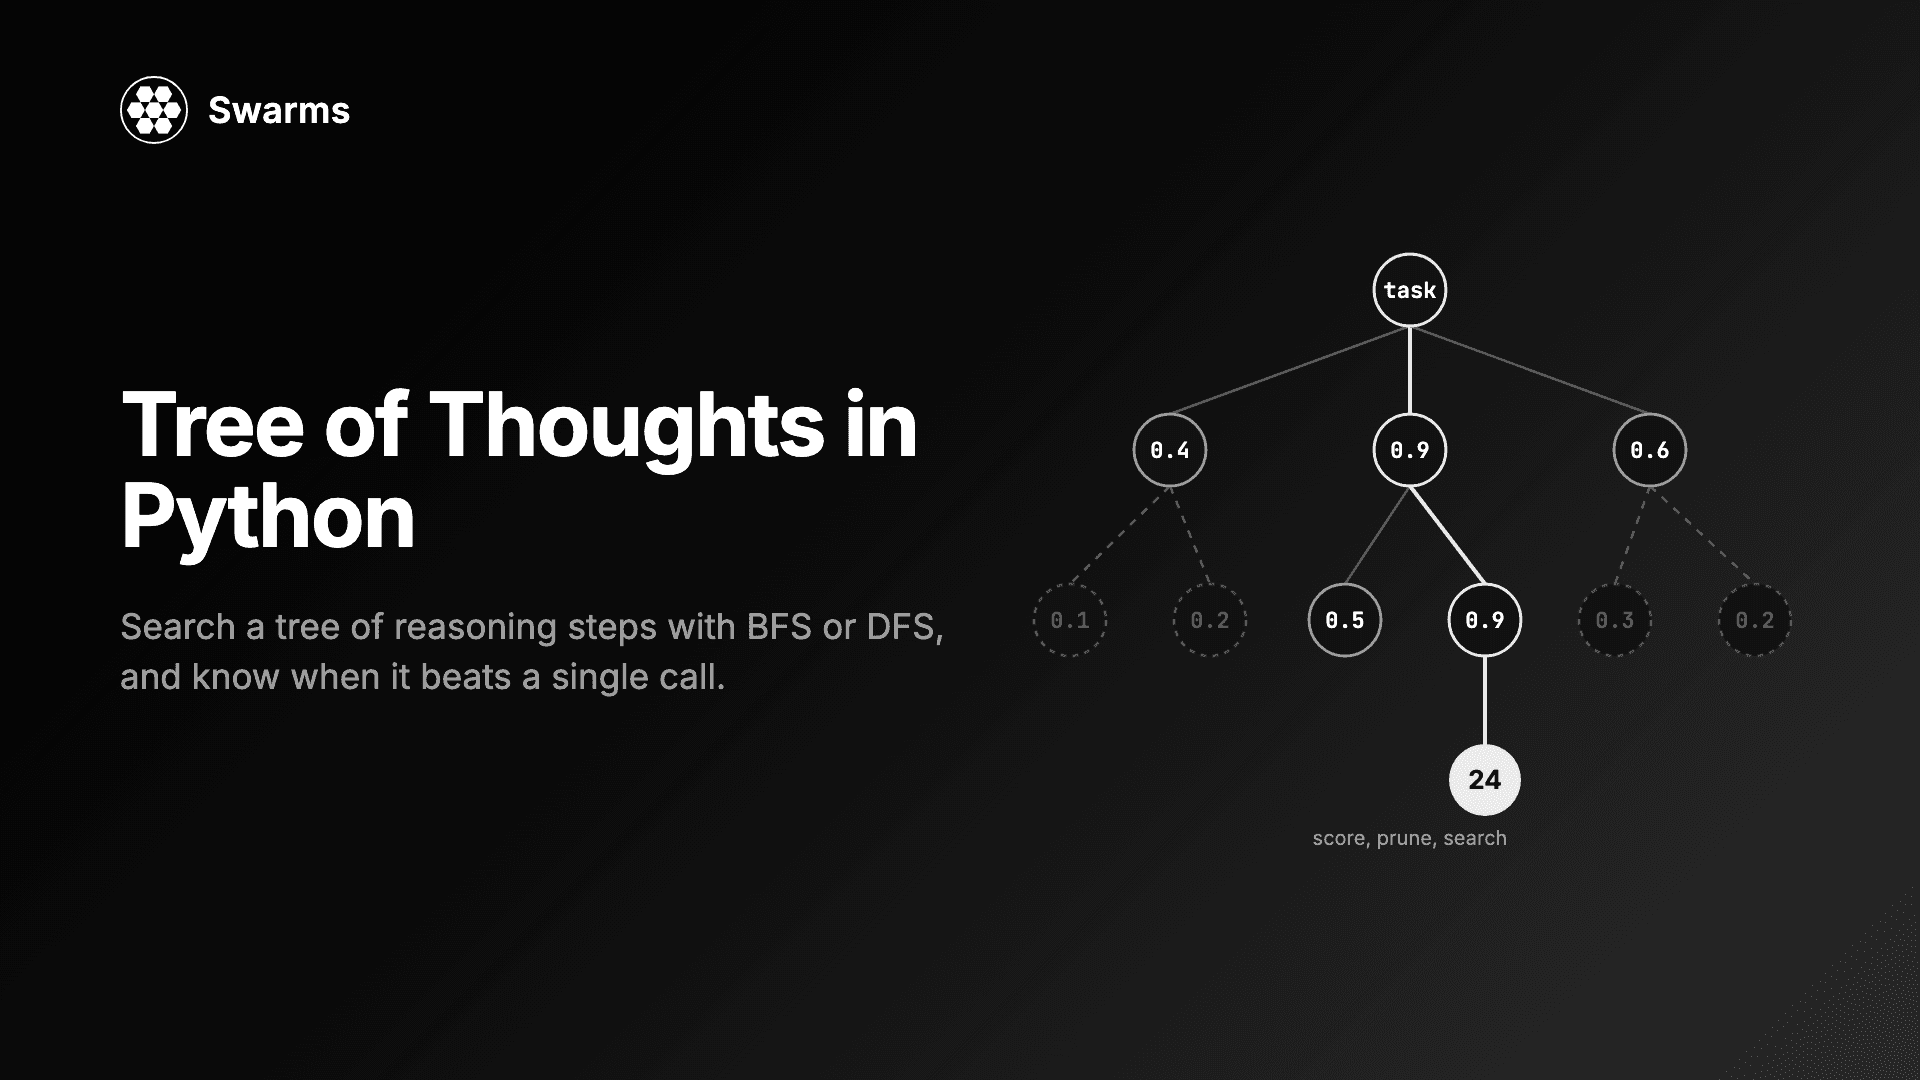
Tree of Thoughts (Yao et al., NeurIPS 2023) generalizes chain-of-thought prompting. Chain of thought writes one line of reasoning from start to finish. ToT treats each intermediate step, a "thought", as a node in a tree and adds three things around the model:
- A thought generator that produces several candidate next steps from a partial solution, either by sampling them independently or by proposing them together in one prompt.
- A state evaluator that uses the model to judge how promising each partial solution is, either by rating each one on its own (value) or by comparing them and voting.
- A search algorithm, breadth-first or depth-first, that decides which nodes to expand next and which to abandon.
In the paper's Game of 24 experiment, GPT-4 with chain-of-thought prompting solved 4% of 100 relatively hard puzzles; ToT with a beam of 5 solved 74%. That accuracy cost more: the paper's appendix reports about 5.5k completion tokens and $0.74 per puzzle for ToT, against $0.47 for 100 chain-of-thought samples, which reached 49% when scored as best of 100. Keep that trade in mind. ToT is LLM search reasoning, and search spends calls.
Install
TreeOfThoughts needs Swarms 16 or later.
pip install -U swarms
# or
uv pip install -U swarms
The examples use an OpenAI model, so set your key in the shell or in a .env file in your working directory, which Swarms loads automatically:
export OPENAI_API_KEY="sk-..."
Check the version:
python -c "import swarms; print(swarms.__version__)"
Any LiteLLM model that supports function calling works. Every model output in TreeOfThoughts is a function call validated against a Pydantic schema, so the search never parses free-form prose.
A first tree of thoughts prompting example: the Game of 24
The Game of 24 gives you four numbers and asks for an expression that uses each exactly once with + - * / to make 24. It is a good first ToT task because it splits cleanly into three steps (each step combines two numbers into one), and a partial solution can be judged: if the numbers left are 1, 1 and 2, the path is dead.
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Game-of-24",
    model_name="gpt-5.4-mini",
    search_algorithm="bfs",
    generation_strategy="propose",
    evaluation_strategy="value",
    num_thoughts=3,
    breadth=2,
    max_depth=3,
    max_expansions=5,
    thought_description=(
        "One arithmetic operation on two of the remaining numbers, written "
        "as 'a op b = c (left: ...)' with the numbers still unused."
    ),
    evaluation_criteria=(
        "Is the arithmetic correct and is every original number used "
        "exactly once? Can the numbers left still reach exactly 24?"
    ),
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Give the expression."
)
print(f"Answer: {answer}\n")

result = agent.last_result
for number, step in enumerate(result.steps, 1):
    print(f"{number}. {step}")
print(
    f"\nsolved={result.solved} nodes_expanded={result.nodes_expanded} "
    f"llm_calls={result.llm_calls}"
)
print(agent.usage)
Our run printed:
Answer: (10 - 4) * (13 - 9) = 24

1. 10 - 4 = 6 (left: 9, 13, 6)
2. 13 - 9 = 4 (left: 6, 4)
3. 6 * 4 = 24 (left: ) Final expression: (10 - 4) * (13 - 9) = 24.

solved=True nodes_expanded=5 llm_calls=21
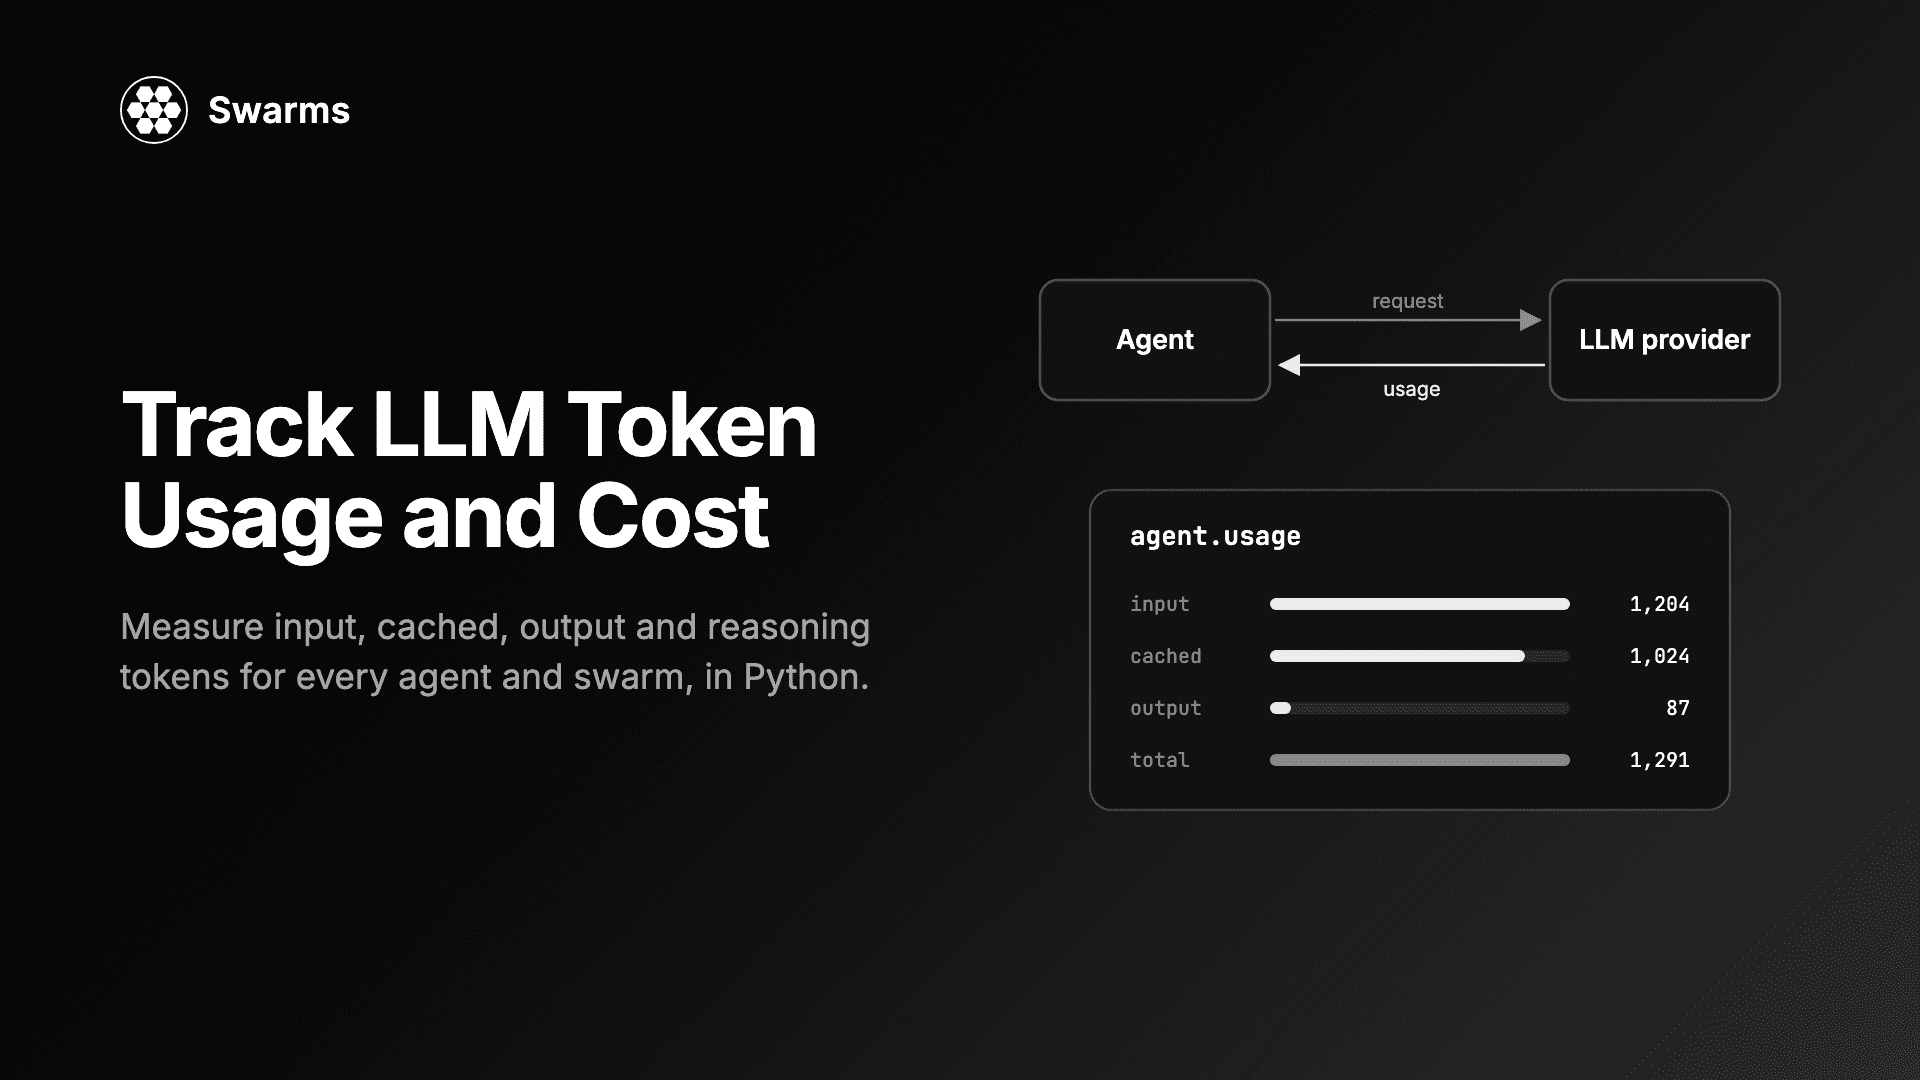
{'input_tokens': 8919, 'output_tokens': 2284, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 11203}
run() returns the answer string (the default output_type="final"). Everything else about the search is on agent.last_result. At LiteLLM's listed price for gpt-5.4-mini ($0.75 per million input tokens, $4.50 per million output tokens), those 11,203 tokens cost about $0.017.
How the tree of thoughts search runs in Python
Each run() repeats four steps until a solution is accepted or the budget runs out:
- Generate. From each node being expanded, ask for
num_thoughts candidate next steps.
- Evaluate. Score each candidate from 0 to 1. Candidates below
value_threshold (default 0.5) are pruned: never expanded and never accepted as the answer.
- Search. Pick which surviving nodes to expand next, breadth-first or depth-first.
- Answer. Write the final answer from the best path. If no final step survived, the answer is completed from the highest-scoring partial path and
solved is False.
Every model call runs on a fresh, stateless Agent that carries only the one function schema it must call, so evaluations never see each other's context. Calls at the same level of the tree run concurrently, up to max_workers (default 8). A call that fails or returns no valid function call is logged as a warning and costs that call's candidates, not the whole search. A step at max_depth is always final, whether or not the model flagged it.
The prompts contain nothing about arithmetic. thought_description tells the generator what one step looks like, and evaluation_criteria tells the evaluator how to judge progress. They are how you adapt the search to a domain, and they matter more than any other setting.
Breadth-first vs depth-first search
search_algorithm="bfs" is a beam search. At each level it expands the best breadth open nodes, evaluates all their children, and keeps the best breadth again. It stops once its best solution scores at least as high as every open partial path. Use it when several partial solutions are worth keeping at once, as in the Game of 24 or a multi-step calculation.
search_algorithm="dfs" follows the best child first, all the way down, and backtracks only when a branch is pruned or exhausted. It returns the first solution it reaches. Use it for case analysis and planning, where you commit to a line and back out on a contradiction. breadth is ignored.
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Game-of-24-DFS",
    model_name="gpt-5.4-mini",
    search_algorithm="dfs",
    num_thoughts=3,
    max_depth=3,
    value_threshold=0.6,
    max_expansions=4,
    thought_description=(
        "One arithmetic operation on two of the remaining numbers, written "
        "as 'a op b = c (left: ...)' with the numbers still unused."
    ),
    evaluation_criteria=(
        "Is the arithmetic correct and is every original number used "
        "exactly once? Can the numbers left still reach exactly 24?"
    ),
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Give the expression."
)
result = agent.last_result
print(f"Answer: {answer}")
print(
    f"solved={result.solved} nodes_expanded={result.nodes_expanded} "
    f"llm_calls={result.llm_calls} tokens={result.usage['total_tokens']}"
)
Answer: 4 * (9 - (13 - 10)) = 24
solved=True nodes_expanded=3 llm_calls=13 tokens=6912
The first branch worked, so DFS expanded three nodes (root, child, grandchild) and stopped: 13 calls against BFS's 21 on the same puzzle. When the first branch fails, DFS backtracks and can spend more than BFS. With no cap it can expand up to 13 nodes at the default num_thoughts=3 and max_depth=3, which is why max_expansions exists.
Propose vs sample, value vs vote
The two other strategy switches map directly to the paper.
| Setting | Option | What it does | Fits |
|---|
generation_strategy | "propose" (default) | One call returns num_thoughts distinct steps | Constrained steps: an equation, a word, a clause |
| "sample" | num_thoughts independent calls, one step each | Open-ended steps: a sentence, a paragraph, a plan |
evaluation_strategy | "value" (default) | Rates each candidate on its own; averages n_evaluate_samples ratings | Steps you can check alone: arithmetic, logic, units |
| "vote" | Shows the candidates side by side; each of n_evaluate_samples calls votes for one | Quality that is relative: writing, estimates |
Vote scores are a candidate's votes divided by the leader's votes, so the leader always scores 1. Two consequences follow from the code. A lone candidate always scores 1, because vote mode cannot reject what it cannot compare. And with n_evaluate_samples=1, every loser scores 0 and is pruned at the default threshold, so only one branch survives per level; raise it to keep more. In BFS, vote mode compares all the candidates at a level in one prompt.
Here is a writing task, the kind the paper ran with sampling and voting, adapted with thought_description and evaluation_criteria:
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Release-Note-Writer",
    model_name="gpt-5.4-mini",
    search_algorithm="bfs",
    generation_strategy="sample",
    evaluation_strategy="vote",
    num_thoughts=3,
    breadth=2,
    max_depth=3,
    n_evaluate_samples=3,
    max_expansions=4,
    thought_description=(
        "One sentence of the release note. The first sentence says what "
        "changed, the second why it matters to the reader, the third what "
        "to do next."
    ),
    evaluation_criteria=(
        "Prefer sentences that are accurate to the facts given, concrete, "
        "and plain. Penalize hype words, vague claims and repetition."
    ),
    agent_kwargs={"max_tokens": 2000},
)

answer = agent.run(
    "Write a three-sentence release note for developers. Facts: Agent.run() "
    "used to return an empty string when every retry of an LLM call failed. "
    "It now raises AgentLLMError after retries and fallback_models are "
    "exhausted. Callers that checked for an empty string should catch the "
    "exception instead."
)
print(answer)

result = agent.last_result
print(f"\nllm_calls={result.llm_calls} usage={result.usage}")
Agent.run() no longer returns an empty string when every retry of an LLM call fails. After retries and fallback_models are exhausted, it now raises AgentLLMError instead of silently returning a blank result. Callers that previously checked for an empty string should catch AgentLLMError and handle the failure path explicitly.

llm_calls=22 usage={'input_tokens': 13199, 'output_tokens': 2044, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 15243}
Twenty-two calls: 12 generator calls (three per expanded node, four nodes), 9 votes (three per level), and the final answer. max_expansions=4 let level three expand one node instead of two. agent_kwargs passes extra Agent arguments, here max_tokens, to every internal call; it cannot override the settings the class depends on, such as the tool schema, max_loops, output_type and system_prompt. To give the search a domain persona, set system_prompt on TreeOfThoughts itself.
The knobs that control cost
Cost in ToT is a count of calls, and the count follows directly from the settings. Per expanded node:
| Generation and evaluation | Calls per expanded node |
|---|
propose + value | 1 + num_thoughts × n_evaluate_samples |
sample + value | num_thoughts × (1 + n_evaluate_samples) |
propose or sample + vote | generator calls as above, plus n_evaluate_samples per comparison |
Add one call for the final answer. With propose and value, llm_calls is at most max_expansions × (1 + num_thoughts × n_evaluate_samples) + 1. Our runs matched: 5 × 4 + 1 = 21 for BFS, 3 × 4 + 1 = 13 for DFS. Fewer evaluations happen when the generator returns duplicates (they are dropped) or fewer candidates than asked.
The levers, in order of effect:
max_expansions caps how many nodes one search may expand. None means no cap. Set it in production.num_thoughts (default 3) multiplies every expansion.n_evaluate_samples (default 1) multiplies every evaluation. More samples give steadier scores.breadth (default 2) and max_depth (default 3) bound the tree. Without a cap, BFS expands at most 1 + breadth × (max_depth − 1) nodes.value_threshold (default 0.5) prunes harder when raised, which cuts expansions and risks discarding the right branch.max_workers (default 8) changes wall time, not cost.temperature defaults to None, so no temperature is sent and the provider default applies. Some models, such as Claude Sonnet 5, reject the parameter. If you set it, keep it above 0 when sampling or averaging several evaluations.
For a full picture of where tokens go across agents and swarms, see how to track LLM token usage and cost in Python.
Inspecting last_result and usage
agent.last_result is a TreeOfThoughtsResult with task, answer, solved, best_node, root (the whole tree), nodes_expanded, llm_calls, usage for that one search, a steps property for the best path, and to_dict(), which serializes everything including the tree. agent.usage is different: it sums tokens over every search the agent has run, with the keys input_tokens, output_tokens, cached_tokens, reasoning_tokens and total_tokens.
Each node in the tree carries content, depth, score, evaluation (the evaluator's critique or the vote tally), is_final, pruned and children. Walking it is the fastest way to see why the search chose what it chose:
import json

from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    model_name="gpt-5.4-mini",
    max_expansions=5,
    thought_description="One arithmetic operation on two of the remaining numbers.",
    evaluation_criteria="Is the arithmetic right? Can the numbers left still reach 24?",
)
agent.run("Use 2, 3, 5 and 12, each exactly once, with + - * / and parentheses to make 24.")
result = agent.last_result


def show(node, indent=0):
    for child in node.children:
        flag = "pruned" if child.pruned else ("final" if child.is_final else "open")
        print(f"{'  ' * indent}[{child.score:.2f} {flag}] {child.content[:70]}")
        show(child, indent + 1)


show(result.root)
print(f"\nsolved={result.solved} answer={result.answer[:200]!r}")

with open("tree.json", "w") as f:
    json.dump(result.to_dict(), f, indent=2)
This is the real output of the run we made, and it is worth reading closely:
[1.00 open] Combine 12 and 2 by division to get 6.
  [0.10 pruned] Combine 6 and 3 by multiplication to get 18.
  [0.50 open] Combine 6 and 5 by multiplication to get 30.
    [0.90 final] Use the current result 30 and the remaining 3 by subtraction: 30 - 3 =
    [0.00 pruned] Use the current result 30 and the remaining 3 by division: 30 / 3 = 10
    [0.90 final] Use the current result 30 and the remaining 3 by subtraction: 30 - 3 =
  [0.20 pruned] Combine 6 and 5 by addition to get 11.
[1.00 open] Combine 12 and 3 by division to get 4.
  [0.50 open] Combine 5 and 4 by multiplication to get 20.
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: subtract 2 to get 18, then
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: add 2 to get 22, then adju
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: divide 20 by 2 to get 10,
  [0.50 open] Combine 5 and 4 by addition to get 9.
  [0.50 open] Combine 5 and 4 by subtraction to get 1.
[0.50 open] Combine 5 and 3 by subtraction to get 2.

solved=True answer='(12 / 2) * (5 - 3) = 24'
The answer is wrong: (12 / 2) × (5 − 3) is 12. tree.json shows what happened. Step three was the last allowed step, so the generator had to finish; it wrote "30 − 3 = 27", noticed that was not 24, and tacked on a new expression. The evaluator gave that step 0.90 and wrote "6 * 2 = 24" in its critique. So solved=True means a final step cleared value_threshold. It does not mean the answer was checked. The search is only as good as its evaluator, and a small model evaluating arithmetic will sometimes approve an error. When the answer can be verified in code, as it can here, verify it. This is one of the failure modes that multi-agent systems share: a component that grades its own work.
When ToT is worth its extra calls, and when a single call is better
To see where the line falls, we ran the same puzzles as single calls: an Agent with max_loops=1 and output_type="final", checking each answer in Python.
from swarms import Agent

agent = Agent(
    agent_name="Single-Call",
    model_name="gpt-5.4-mini",
    max_loops=1,
    output_type="final",
    print_on=False,
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Reply with the expression only."
)
print(answer)
print(agent.usage)
(13-9)*(10-4)
{'input_tokens': 246, 'output_tokens': 12, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 258}
What we measured with gpt-5.4-mini. These are small samples from our own runs, not a benchmark:
| Puzzle | Method | Correct | Calls per attempt | Tokens per attempt |
|---|
| 4, 9, 10, 13 | Single call | 8 of 10 | 1 | about 258 |
| 4, 9, 10, 13 | ToT, BFS and DFS above | 2 of 2 | 21 and 13 | 11,203 and 6,912 |
| 2, 3, 5, 12 | Single call | 5 of 10 | 1 | about 258 |
| 2, 3, 5, 12 | ToT, max_expansions=5 | 4 of 10 (BFS 2 of 5, DFS 2 of 5); two of the four first stated a wrong expression | 21 | about 11,300 |
On the easier puzzle, where a single call was right 8 times in 10, ToT was right both times we ran it, at roughly 25 to 45 times the tokens. On the harder one, ToT with this small model and this small budget did no better than a single call, and the one run that reported solved=True had the wrong answer. Spending over 40 times the tokens bought nothing there.
That points to a rule of thumb:
- Use ToT when a single pass fails often, the task splits into steps that can be judged one at a time, and your model is a reliable judge of those steps. A stronger model, more
n_evaluate_samples, or a wider beam all buy accuracy with calls.
- Use a single call when the model already answers correctly most of the time, when latency matters, or when the answer can be checked in code. A check plus a retry is often cheaper than a search.
- Use voting across independent answers (for example
MajorityVoting) when answers are discrete and you want noise reduction without step-level evaluation.
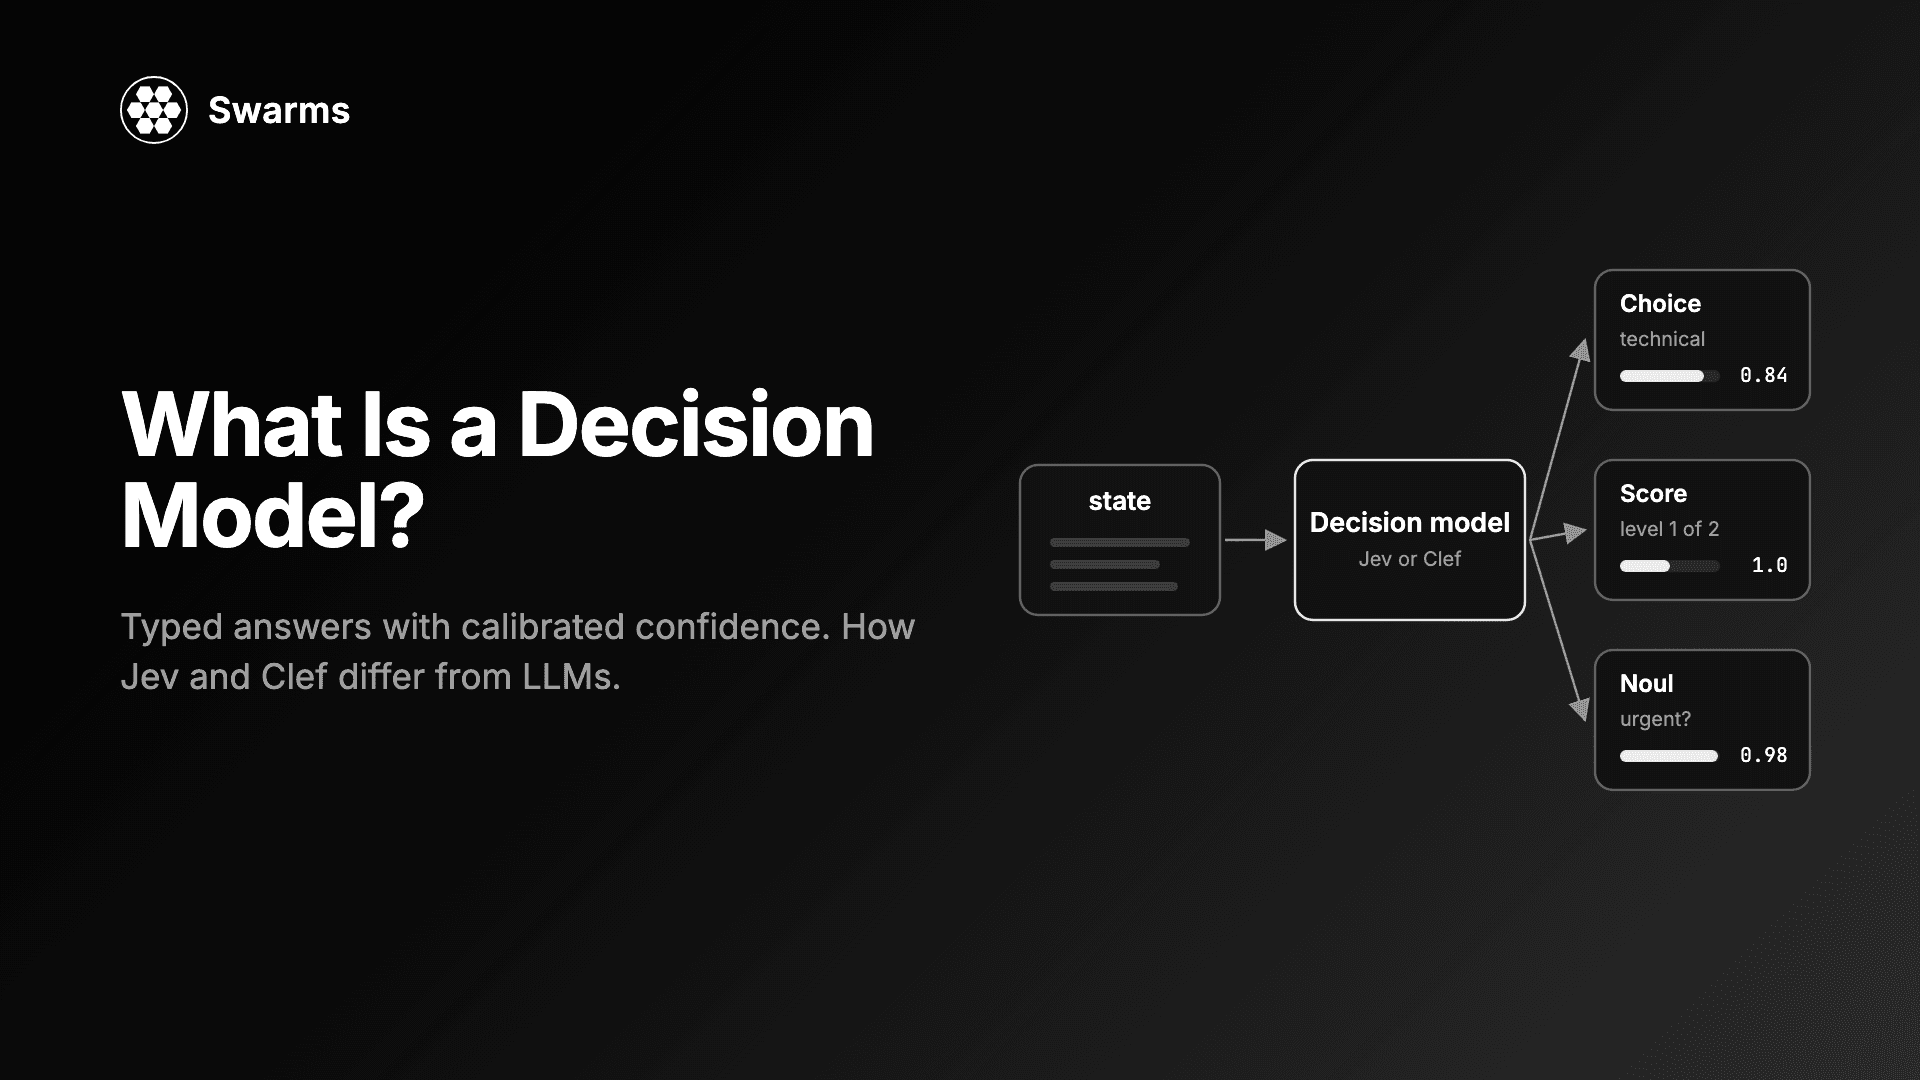
Deciding between those per request is itself a routing decision; what a decision model is and how a decision model reduces LLM costs cover that layer. For when one agent is enough and when structure helps, see what an agent is and agentic AI explained. When the steps of a task are known in advance, a fixed graph is cheaper than a search; the GraphWorkflow paper describes that engine.
FAQ
How do I implement tree of thoughts in Python?
Install Swarms 16 or later, then from swarms import TreeOfThoughts, create the agent with a function-calling model, and call run(task). Set thought_description and evaluation_criteria for your domain and max_expansions to cap cost. The examples in examples/reasoning_agents/tree_of_thoughts_examples/ cover mathematics, physics and logic puzzles.
What is the difference between tree of thoughts and chain of thought?
Chain of thought writes one reasoning path in one call. Tree of thoughts generates several candidate steps, has the model evaluate them, prunes weak ones, and searches for the best path, with backtracking in DFS. It costs many calls per task instead of one.
How many LLM calls does a ToT LLM run make?
With propose and value, at most max_expansions × (1 + num_thoughts × n_evaluate_samples) + 1. Our Game of 24 runs made 21 calls with BFS and 13 with DFS. agent.last_result.llm_calls reports the count for each search, failed calls included.
Does tree of thoughts work with Claude or Gemini?
Yes, with any LiteLLM model that supports function calling: set model_name. Leave temperature unset for models that reject it, such as Claude Sonnet 5.
Does solved=True mean the answer is correct?
No. It means a final step scored at least value_threshold with the model's own evaluator. Verify the answer in code when you can.
The TreeOfThoughts source is swarms/agents/tree_of_thoughts.py on GitHub, and the full v16 changelog is in the Swarms v16 Overclock release notes. Questions? Join our Discord community.