指南工程
用 Python 实现 Tree of Thoughts:实用实现指南
用 Swarms 在 Python 中实现 tree of thoughts:求解 24 点游戏,对比 BFS 与 DFS、propose 与 sample、value 与 vote,控制成本,并查看真实的调用次数。
Swarms 团队11 分钟阅读

用 Swarms 在 Python 中实现 tree of thoughts:求解 24 点游戏,对比 BFS 与 DFS、propose 与 sample、value 与 vote,控制成本,并查看真实的调用次数。
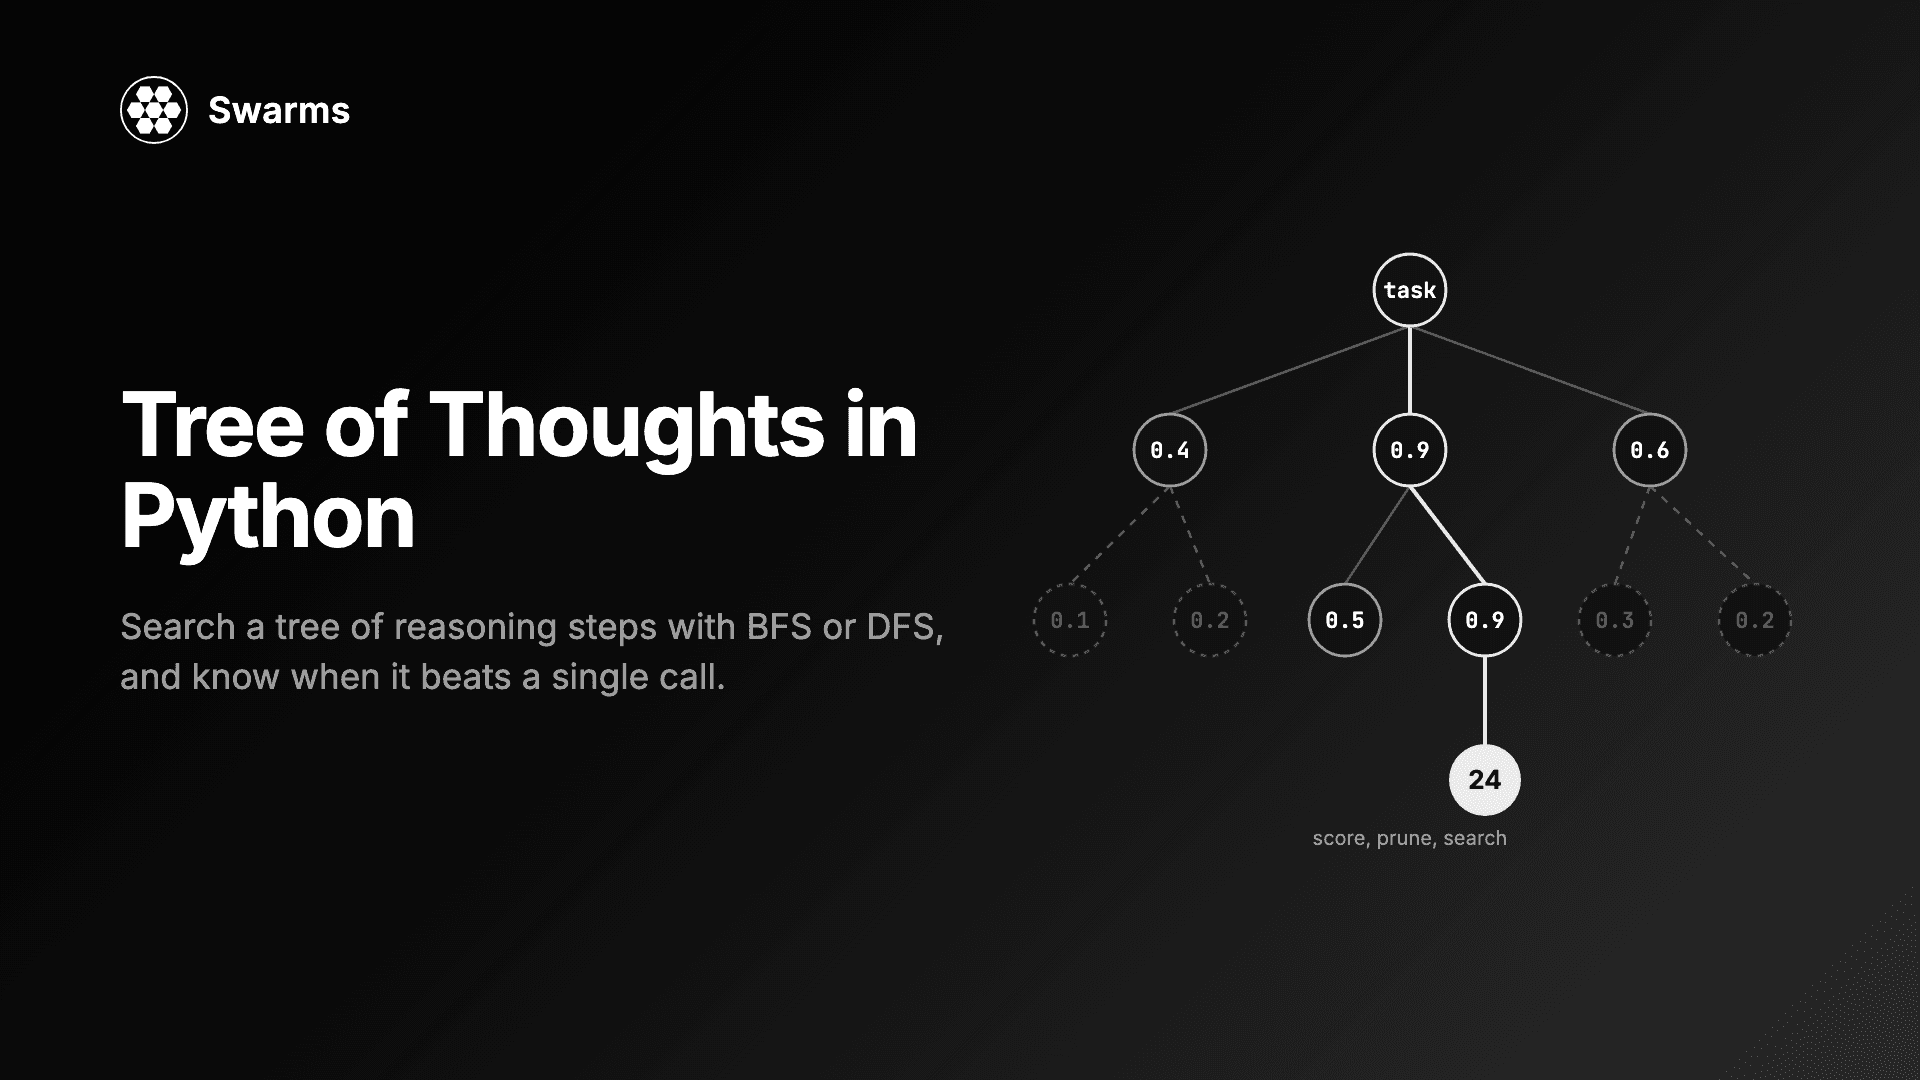
一次 LLM 调用会认定它想到的第一个思路。如果第一步错了,后面的每一步都建立在这个错误之上,没有任何环节回头检查。Tree of Thoughts(ToT,思维树)用一次搜索取代这种一次性推理:模型提出若干个候选的下一步,给它们打分,丢掉弱的,再从最好的那个继续。本指南展示如何用 Swarms v16 中发布的 TreeOfThoughts 智能体在 Python 中运行 tree of thoughts,从原论文里的 24 点游戏(Game of 24)开始。下文的每一个数字都来自我们用 gpt-5.4-mini 做的实际运行,包括 ToT 答错的那些。
Tree of Thoughts(Yao 等,NeurIPS 2023)是对 chain-of-thought(思维链)提示的推广。思维链从头到尾写出一条推理线。ToT 把每一个中间步骤,也就是一个“thought”,当作树上的一个节点,并在模型周围加上三样东西:
在论文的 24 点实验中,使用思维链提示的 GPT-4 在 100 道相对较难的题目里只解出了 4%;束宽为 5 的 ToT 解出了 74%。这种准确率是有代价的:论文附录报告,ToT 每道题大约需要 5.5k 个补全 token、花费 0.74 美元,而 100 次思维链采样的花费是 0.47 美元,按 100 次取最好计算的成功率是 49%。请记住这笔账。ToT 是 LLM 的搜索式推理,而搜索要花调用次数。
TreeOfThoughts 需要 Swarms 16 或更高版本。
pip install -U swarms
# or
uv pip install -U swarms
示例使用 OpenAI 模型,所以请在 shell 中设置密钥,或者写进工作目录下的 .env 文件,Swarms 会自动加载它:
export OPENAI_API_KEY="sk-..."检查版本:
python -c "import swarms; print(swarms.__version__)"任何支持函数调用的 LiteLLM 模型都可以使用。TreeOfThoughts 中模型的每一次输出都是一次按 Pydantic schema 校验的函数调用,所以搜索过程从不解析自由格式的文本。
24 点游戏给你四个数字,要求用 + - * / 写出一个每个数字恰好用一次、结果为 24 的表达式。它很适合作为第一个 ToT 任务,因为它能干净地拆成三步(每一步把两个数合并成一个),而且部分解是可以判断的:如果剩下的数是 1、1 和 2,这条路就走不通了。
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Game-of-24",
    model_name="gpt-5.4-mini",
    search_algorithm="bfs",
    generation_strategy="propose",
    evaluation_strategy="value",
    num_thoughts=3,
    breadth=2,
    max_depth=3,
    max_expansions=5,
    thought_description=(
        "One arithmetic operation on two of the remaining numbers, written "
        "as 'a op b = c (left: ...)' with the numbers still unused."
    ),
    evaluation_criteria=(
        "Is the arithmetic correct and is every original number used "
        "exactly once? Can the numbers left still reach exactly 24?"
    ),
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Give the expression."
)
print(f"Answer: {answer}\n")

result = agent.last_result
for number, step in enumerate(result.steps, 1):
    print(f"{number}. {step}")
print(
    f"\nsolved={result.solved} nodes_expanded={result.nodes_expanded} "
    f"llm_calls={result.llm_calls}"
)
print(agent.usage)
我们的运行输出:
Answer: (10 - 4) * (13 - 9) = 24

1. 10 - 4 = 6 (left: 9, 13, 6)
2. 13 - 9 = 4 (left: 6, 4)
3. 6 * 4 = 24 (left: ) Final expression: (10 - 4) * (13 - 9) = 24.

solved=True nodes_expanded=5 llm_calls=21
{'input_tokens': 8919, 'output_tokens': 2284, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 11203}
run() 返回答案字符串(默认 output_type="final")。关于这次搜索的其余一切都在 agent.last_result 上。按 LiteLLM 列出的 gpt-5.4-mini 价格(每百万输入 token 0.75 美元,每百万输出 token 4.50 美元)计算,这 11,203 个 token 大约花费 0.017 美元。
每次 run() 都会重复四个步骤,直到有一个解被接受,或者预算耗尽:
num_thoughts 个候选的下一步。value_threshold(默认 0.5)的候选会被剪枝:永远不会被展开,也永远不会被接受为答案。solved 为 False。每一次模型调用都运行在一个全新的、无状态的 Agent 上,它只携带必须调用的那一个函数 schema,所以各次评估永远看不到彼此的上下文。树上同一层的调用会并发执行,最多 max_workers 个(默认 8)。失败的调用,或者没有返回有效函数调用的调用,会被记录为警告,损失的只是这次调用的候选,而不是整个搜索。位于 max_depth 的步骤总是最终步骤,无论模型有没有这样标记它。
提示词里没有任何关于算术的内容。thought_description 告诉生成器一步是什么样子,evaluation_criteria 告诉评估器如何判断进展。它们是让搜索适配某个领域的方式,比任何其他设置都更重要。
search_algorithm="bfs" 是一种束搜索(beam search)。在每一层,它展开最好的 breadth 个开放节点,评估它们的全部子节点,再保留最好的 breadth 个。一旦它的最佳解得分不低于每一条开放的部分路径,它就停止。当同时有多个部分解值得保留时使用它,比如 24 点游戏或多步计算。
search_algorithm="dfs" 先沿着最好的子节点一路走到底,只有在某个分支被剪枝或耗尽时才回溯。它返回遇到的第一个解。它适合分情况讨论和规划这类任务:先认定一条路线,遇到矛盾再退回来。breadth 会被忽略。
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Game-of-24-DFS",
    model_name="gpt-5.4-mini",
    search_algorithm="dfs",
    num_thoughts=3,
    max_depth=3,
    value_threshold=0.6,
    max_expansions=4,
    thought_description=(
        "One arithmetic operation on two of the remaining numbers, written "
        "as 'a op b = c (left: ...)' with the numbers still unused."
    ),
    evaluation_criteria=(
        "Is the arithmetic correct and is every original number used "
        "exactly once? Can the numbers left still reach exactly 24?"
    ),
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Give the expression."
)
result = agent.last_result
print(f"Answer: {answer}")
print(
    f"solved={result.solved} nodes_expanded={result.nodes_expanded} "
    f"llm_calls={result.llm_calls} tokens={result.usage['total_tokens']}"
)
Answer: 4 * (9 - (13 - 10)) = 24
solved=True nodes_expanded=3 llm_calls=13 tokens=6912
第一个分支就成功了,所以 DFS 只展开了三个节点(根节点、子节点、孙节点)就停止了:同一道题,13 次调用,而 BFS 是 21 次。当第一个分支失败时,DFS 会回溯,花费可能超过 BFS。在默认的 num_thoughts=3 和 max_depth=3 下,如果不设上限,它最多可以展开 13 个节点,这正是 max_expansions 存在的原因。
另外两个策略开关与论文一一对应。
| 设置 | 选项 | 作用 | 适用场景 |
|---|---|---|---|
generation_strategy | "propose"(默认) | 一次调用返回 num_thoughts 个不同的步骤 | 受约束的步骤:一个等式、一个词、一个子句 |
"sample" | num_thoughts 次独立调用,每次一个步骤 | 开放式的步骤:一句话、一段话、一个计划 | |
evaluation_strategy | "value"(默认) | 逐个单独给候选打分;对 n_evaluate_samples 次打分取平均 | 可以单独检查的步骤:算术、逻辑、单位 |
"vote" | 把候选并排展示;n_evaluate_samples 次调用中每次投票给一个 | 质量是相对的:写作、估算 |
投票得分是一个候选的票数除以领先者的票数,所以领先者总是得 1 分。从代码可以推出两个后果。单独一个候选总是得 1 分,因为投票模式无法否决一个没有比较对象的候选。而在 n_evaluate_samples=1 时,每个落选者都得 0 分,在默认阈值下会被剪枝,所以每层只有一个分支存活;调高它可以保留更多分支。在 BFS 中,投票模式会在一个提示里比较同一层的全部候选。
下面是一个写作任务,也就是论文中用采样加投票来做的那类任务,用 thought_description 和 evaluation_criteria 做了适配:
from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    name="Release-Note-Writer",
    model_name="gpt-5.4-mini",
    search_algorithm="bfs",
    generation_strategy="sample",
    evaluation_strategy="vote",
    num_thoughts=3,
    breadth=2,
    max_depth=3,
    n_evaluate_samples=3,
    max_expansions=4,
    thought_description=(
        "One sentence of the release note. The first sentence says what "
        "changed, the second why it matters to the reader, the third what "
        "to do next."
    ),
    evaluation_criteria=(
        "Prefer sentences that are accurate to the facts given, concrete, "
        "and plain. Penalize hype words, vague claims and repetition."
    ),
    agent_kwargs={"max_tokens": 2000},
)

answer = agent.run(
    "Write a three-sentence release note for developers. Facts: Agent.run() "
    "used to return an empty string when every retry of an LLM call failed. "
    "It now raises AgentLLMError after retries and fallback_models are "
    "exhausted. Callers that checked for an empty string should catch the "
    "exception instead."
)
print(answer)

result = agent.last_result
print(f"\nllm_calls={result.llm_calls} usage={result.usage}")
Agent.run() no longer returns an empty string when every retry of an LLM call fails. After retries and fallback_models are exhausted, it now raises AgentLLMError instead of silently returning a blank result. Callers that previously checked for an empty string should catch AgentLLMError and handle the failure path explicitly.
llm_calls=22 usage={'input_tokens': 13199, 'output_tokens': 2044, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 15243}
二十二次调用:12 次生成调用(每个展开节点 3 次,共 4 个节点),9 次投票(每层 3 次),加上最终答案。max_expansions=4 让第三层只展开了一个节点而不是两个。agent_kwargs 把额外的 Agent 参数(这里是 max_tokens)传给每一次内部调用;它不能覆盖这个类所依赖的设置,比如工具 schema、max_loops、output_type 和 system_prompt。要给搜索设定一个领域角色,请直接在 TreeOfThoughts 上设置 system_prompt。
ToT 的成本就是调用次数,而调用次数直接由设置决定。每个展开节点的调用次数:
| 生成与评估 | 每个展开节点的调用次数 |
|---|---|
propose + value | 1 + num_thoughts × n_evaluate_samples |
sample + value | num_thoughts × (1 + n_evaluate_samples) |
propose 或 sample + vote | 生成调用同上,再加上每次比较 n_evaluate_samples 次 |
最终答案再加一次调用。使用 propose 和 value 时,llm_calls 最多为 max_expansions × (1 + num_thoughts × n_evaluate_samples) + 1。我们的运行与之吻合:BFS 是 5 × 4 + 1 = 21,DFS 是 3 × 4 + 1 = 13。当生成器返回重复的候选(会被丢弃),或者返回的候选少于请求数量时,评估次数会更少。
按影响大小排列的调节手段:
max_expansions 限制一次搜索最多能展开多少个节点。None 表示不设上限。生产环境中请设置它。num_thoughts(默认 3)会乘到每一次展开上。n_evaluate_samples(默认 1)会乘到每一次评估上。样本越多,分数越稳定。breadth(默认 2)和 max_depth(默认 3)限定了树的大小。不设上限时,BFS 最多展开 1 + breadth × (max_depth − 1) 个节点。value_threshold(默认 0.5)调高后剪枝更狠,能减少展开次数,但有丢掉正确分支的风险。max_workers(默认 8)改变的是耗时,而不是成本。temperature 默认为 None,即不发送 temperature,使用 provider 的默认值。有些模型,比如 Claude Sonnet 5,会拒绝这个参数。如果你设置了它,在采样或对多次评估取平均时,请让它大于 0。想全面了解 token 在各个智能体和 swarm 之间花在了哪里,请看如何在 Python 中追踪 LLM 的 token 用量与成本。
agent.last_result 是一个 TreeOfThoughtsResult,包含 task、answer、solved、best_node、root(整棵树)、nodes_expanded、llm_calls、这一次搜索的 usage、表示最佳路径的 steps 属性,以及会把包括整棵树在内的一切序列化的 to_dict()。agent.usage 则不同:它对这个智能体运行过的每一次搜索的 token 求和,键为 input_tokens、output_tokens、cached_tokens、reasoning_tokens 和 total_tokens。
树上的每个节点都带有 content、depth、score、evaluation(评估器的点评或投票计数)、is_final、pruned 和 children。遍历它是弄清搜索为什么做出某个选择的最快方法:
import json

from swarms import TreeOfThoughts

agent = TreeOfThoughts(
    model_name="gpt-5.4-mini",
    max_expansions=5,
    thought_description="One arithmetic operation on two of the remaining numbers.",
    evaluation_criteria="Is the arithmetic right? Can the numbers left still reach 24?",
)
agent.run("Use 2, 3, 5 and 12, each exactly once, with + - * / and parentheses to make 24.")
result = agent.last_result


def show(node, indent=0):
    for child in node.children:
        flag = "pruned" if child.pruned else ("final" if child.is_final else "open")
        print(f"{'  ' * indent}[{child.score:.2f} {flag}] {child.content[:70]}")
        show(child, indent + 1)


show(result.root)
print(f"\nsolved={result.solved} answer={result.answer[:200]!r}")

with open("tree.json", "w") as f:
    json.dump(result.to_dict(), f, indent=2)
下面是我们那次运行的真实输出,值得仔细读一读:
[1.00 open] Combine 12 and 2 by division to get 6.
  [0.10 pruned] Combine 6 and 3 by multiplication to get 18.
  [0.50 open] Combine 6 and 5 by multiplication to get 30.
    [0.90 final] Use the current result 30 and the remaining 3 by subtraction: 30 - 3 =
    [0.00 pruned] Use the current result 30 and the remaining 3 by division: 30 / 3 = 10
    [0.90 final] Use the current result 30 and the remaining 3 by subtraction: 30 - 3 =
  [0.20 pruned] Combine 6 and 5 by addition to get 11.
[1.00 open] Combine 12 and 3 by division to get 4.
  [0.50 open] Combine 5 and 4 by multiplication to get 20.
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: subtract 2 to get 18, then
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: add 2 to get 22, then adju
    [0.00 pruned] Use the 20 from step 2 and the remaining 2: divide 20 by 2 to get 10,
  [0.50 open] Combine 5 and 4 by addition to get 9.
  [0.50 open] Combine 5 and 4 by subtraction to get 1.
[0.50 open] Combine 5 and 3 by subtraction to get 2.

solved=True answer='(12 / 2) * (5 - 3) = 24'
这个答案是错的:(12 / 2) × (5 − 3) 等于 12。tree.json 显示了事情的经过。第三步是允许的最后一步,所以生成器必须收尾;它写出了“30 − 3 = 27”,发现这不是 24,又接上了一个新的表达式。评估器给这一步打了 0.90 分,还在点评里写了“6 * 2 = 24”。所以 solved=True 的意思是有一个最终步骤越过了 value_threshold,并不表示答案经过了检验。搜索的质量取决于它的评估器,而一个评估算术的小模型有时会认可一个错误。当答案可以用代码验证时,就像这里一样,请用代码验证。这是多智能体系统共有的失败模式之一:由一个组件给自己的工作打分。
为了看清界线在哪里,我们把同样的题目作为单次调用来跑:一个 max_loops=1、output_type="final" 的 Agent,并在 Python 中检查每个答案。
from swarms import Agent

agent = Agent(
    agent_name="Single-Call",
    model_name="gpt-5.4-mini",
    max_loops=1,
    output_type="final",
    print_on=False,
)

answer = agent.run(
    "Use the numbers 4, 9, 10 and 13, each exactly once, with + - * / "
    "and parentheses to make 24. Reply with the expression only."
)
print(answer)
print(agent.usage)
(13-9)*(10-4)
{'input_tokens': 246, 'output_tokens': 12, 'cached_tokens': 0, 'reasoning_tokens': 0, 'total_tokens': 258}
我们用 gpt-5.4-mini 测得的结果。这些是我们自己运行得到的小样本,不是基准测试:
| 题目 | 方法 | 正确 | 每次尝试的调用次数 | 每次尝试的 token 数 |
|---|---|---|---|---|
| 4, 9, 10, 13 | 单次调用 | 10 次中 8 次 | 1 | 约 258 |
| 4, 9, 10, 13 | ToT,上文的 BFS 与 DFS | 2 次中 2 次 | 21 和 13 | 11,203 和 6,912 |
| 2, 3, 5, 12 | 单次调用 | 10 次中 5 次 | 1 | 约 258 |
| 2, 3, 5, 12 | ToT,max_expansions=5 | 10 次中 4 次(BFS 5 次中 2 次,DFS 5 次中 2 次);这 4 次中有 2 次先给出了一个错误的表达式 | 21 | 约 11,300 |
在较简单的那道题上,单次调用 10 次里对 8 次,而 ToT 在我们运行的两次里都答对了,代价大约是 25 到 45 倍的 token。在较难的那道题上,用这个小模型和这么小的预算,ToT 并不比单次调用好,而且唯一一次报告 solved=True 的运行给出的是错误答案。在那里,多花 40 多倍的 token 什么也没换来。
由此可以得出一条经验法则:
n_evaluate_samples 或更宽的束,都是用调用次数换取准确率。MajorityVoting):当答案是离散的,你想在不做逐步评估的情况下降低噪声时。针对每个请求在这些方案之间做选择,本身就是一个路由决策;什么是决策模型和如何用决策模型降低 LLM 成本讲的就是这一层。至于什么时候一个智能体就够、什么时候需要结构,请看什么是智能体和智能体 AI 详解。当任务的步骤事先已知时,固定的图比搜索更便宜;GraphWorkflow 论文介绍了那个引擎。
如何用 Python 实现 tree of thoughts?
安装 Swarms 16 或更高版本,然后 from swarms import TreeOfThoughts,用一个支持函数调用的模型创建智能体,再调用 run(task)。为你的领域设置 thought_description 和 evaluation_criteria,并用 max_expansions 限制成本。examples/reasoning_agents/tree_of_thoughts_examples/ 中的示例涵盖数学、物理和逻辑谜题。
Tree of thoughts 和 chain of thought 有什么区别? Chain of thought 在一次调用中写出一条推理路径。Tree of thoughts 生成多个候选步骤,让模型评估它们,剪掉弱的,并搜索最佳路径,在 DFS 中还会回溯。每个任务要花很多次调用,而不是一次。
一次 ToT LLM 运行会发起多少次 LLM 调用?
使用 propose 和 value 时,最多 max_expansions × (1 + num_thoughts × n_evaluate_samples) + 1 次。我们的 24 点运行中,BFS 发起了 21 次调用,DFS 发起了 13 次。agent.last_result.llm_calls 会报告每次搜索的调用次数,失败的调用也计算在内。
Tree of thoughts 能用于 Claude 或 Gemini 吗?
可以,任何支持函数调用的 LiteLLM 模型都行:设置 model_name 即可。对于会拒绝 temperature 的模型,比如 Claude Sonnet 5,请不要设置它。
solved=True 是否表示答案正确?
不是。它表示有一个最终步骤在模型自己的评估器下得分不低于 value_threshold。能用代码验证答案时,请验证。
TreeOfThoughts 的源码位于 GitHub 上的 swarms/agents/tree_of_thoughts.py,完整的 v16 更新日志见 Swarms v16 Overclock 发布说明。有问题?欢迎加入我们的 Discord 社区。
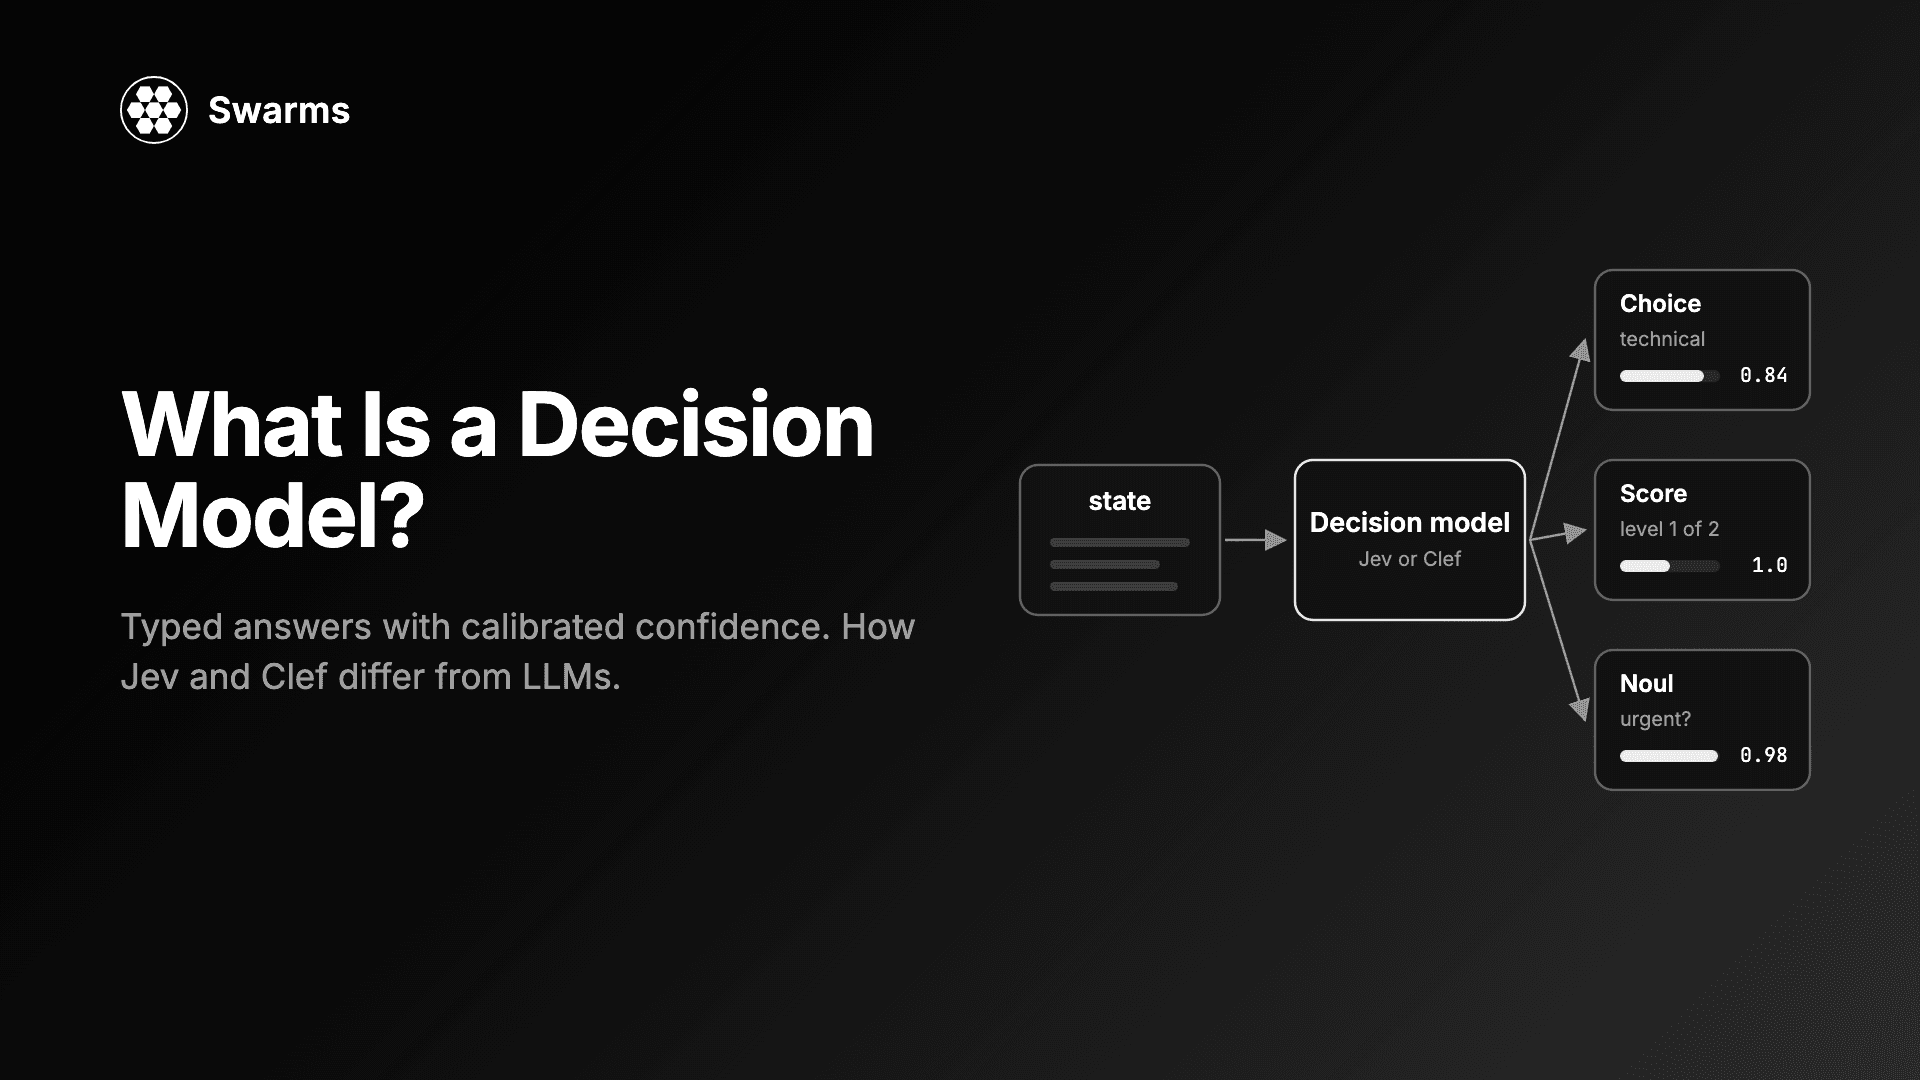
什么是决策模型?TypeSafe Jev 与 Cloudflare Clef 如何用经过校准的置信度回答带类型的问题,而不是生成文本,以及如何在 Swarms 中使用它们。
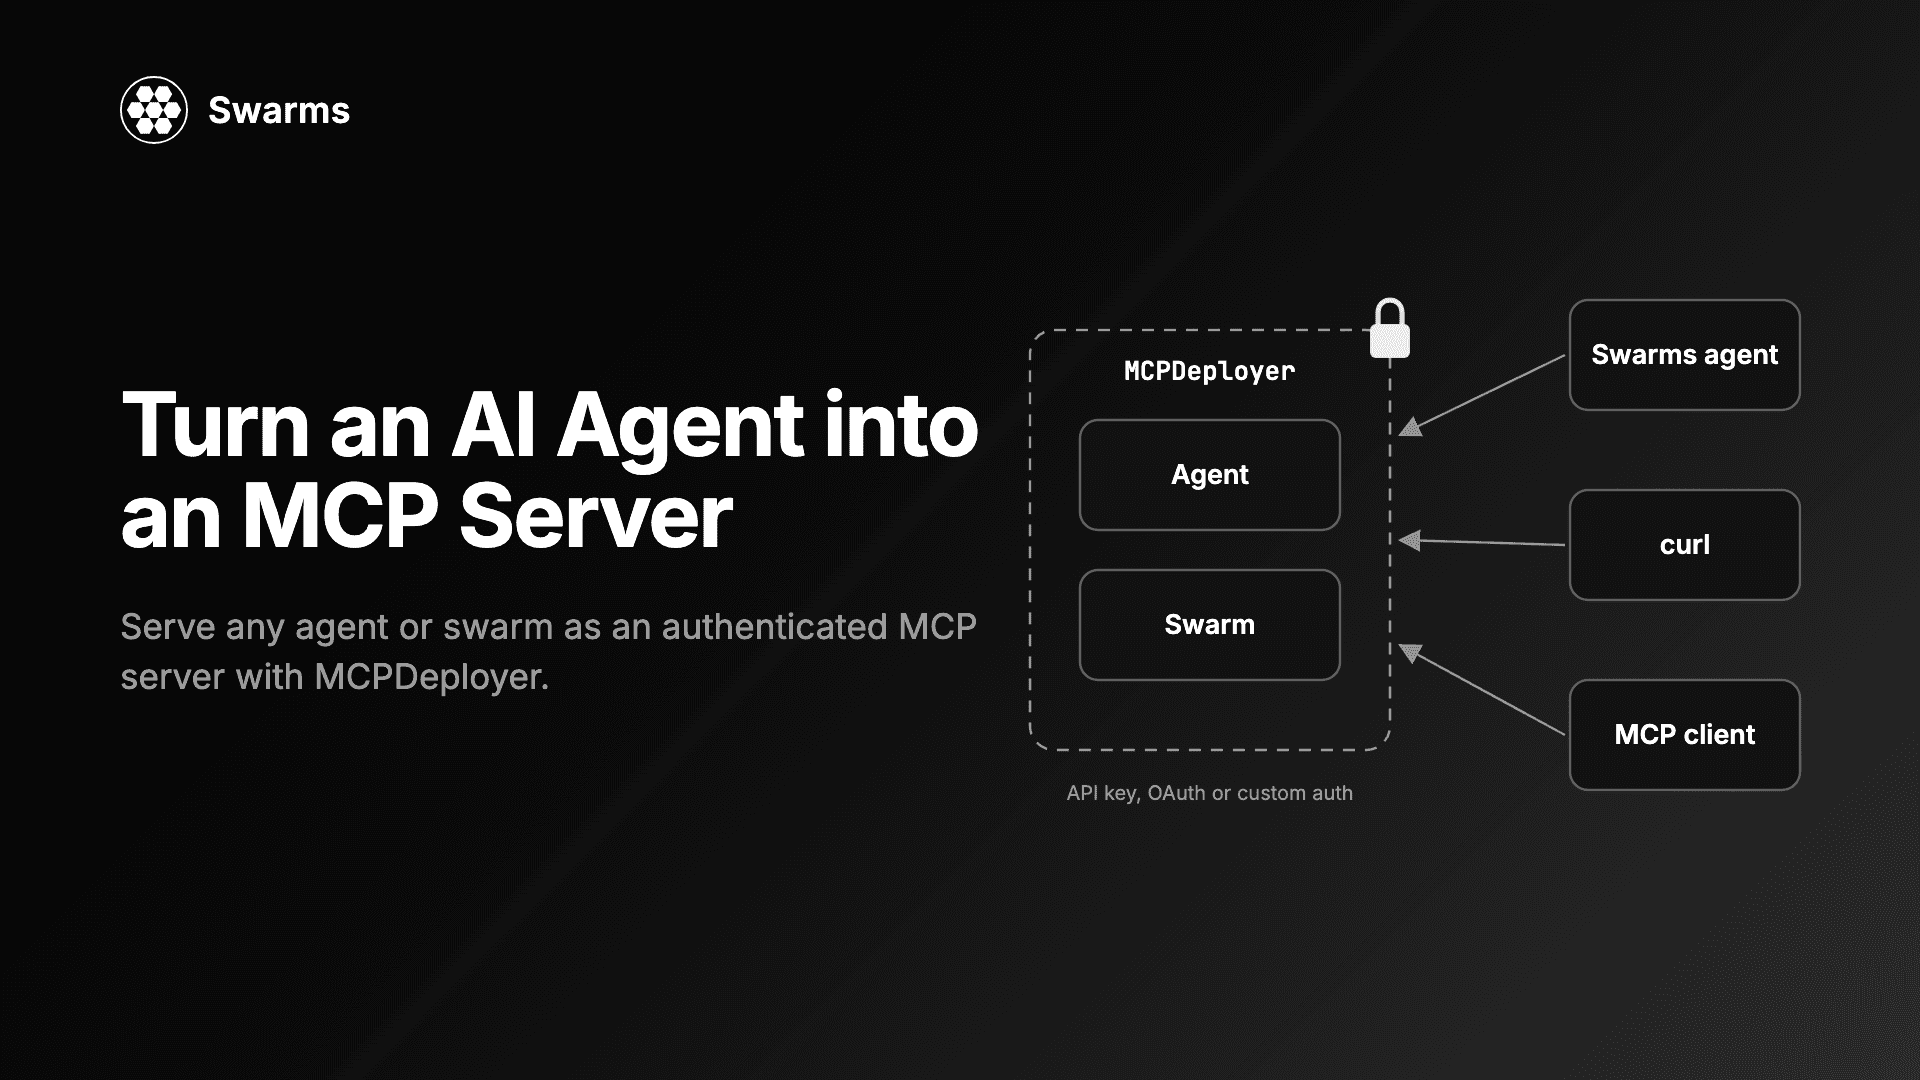
用 Swarms MCPDeployer 在 Python 中把 AI 智能体变成 MCP 服务器:API key、自定义认证、token 校验器、把 swarm 作为工具,以及一个调用它的客户端智能体。
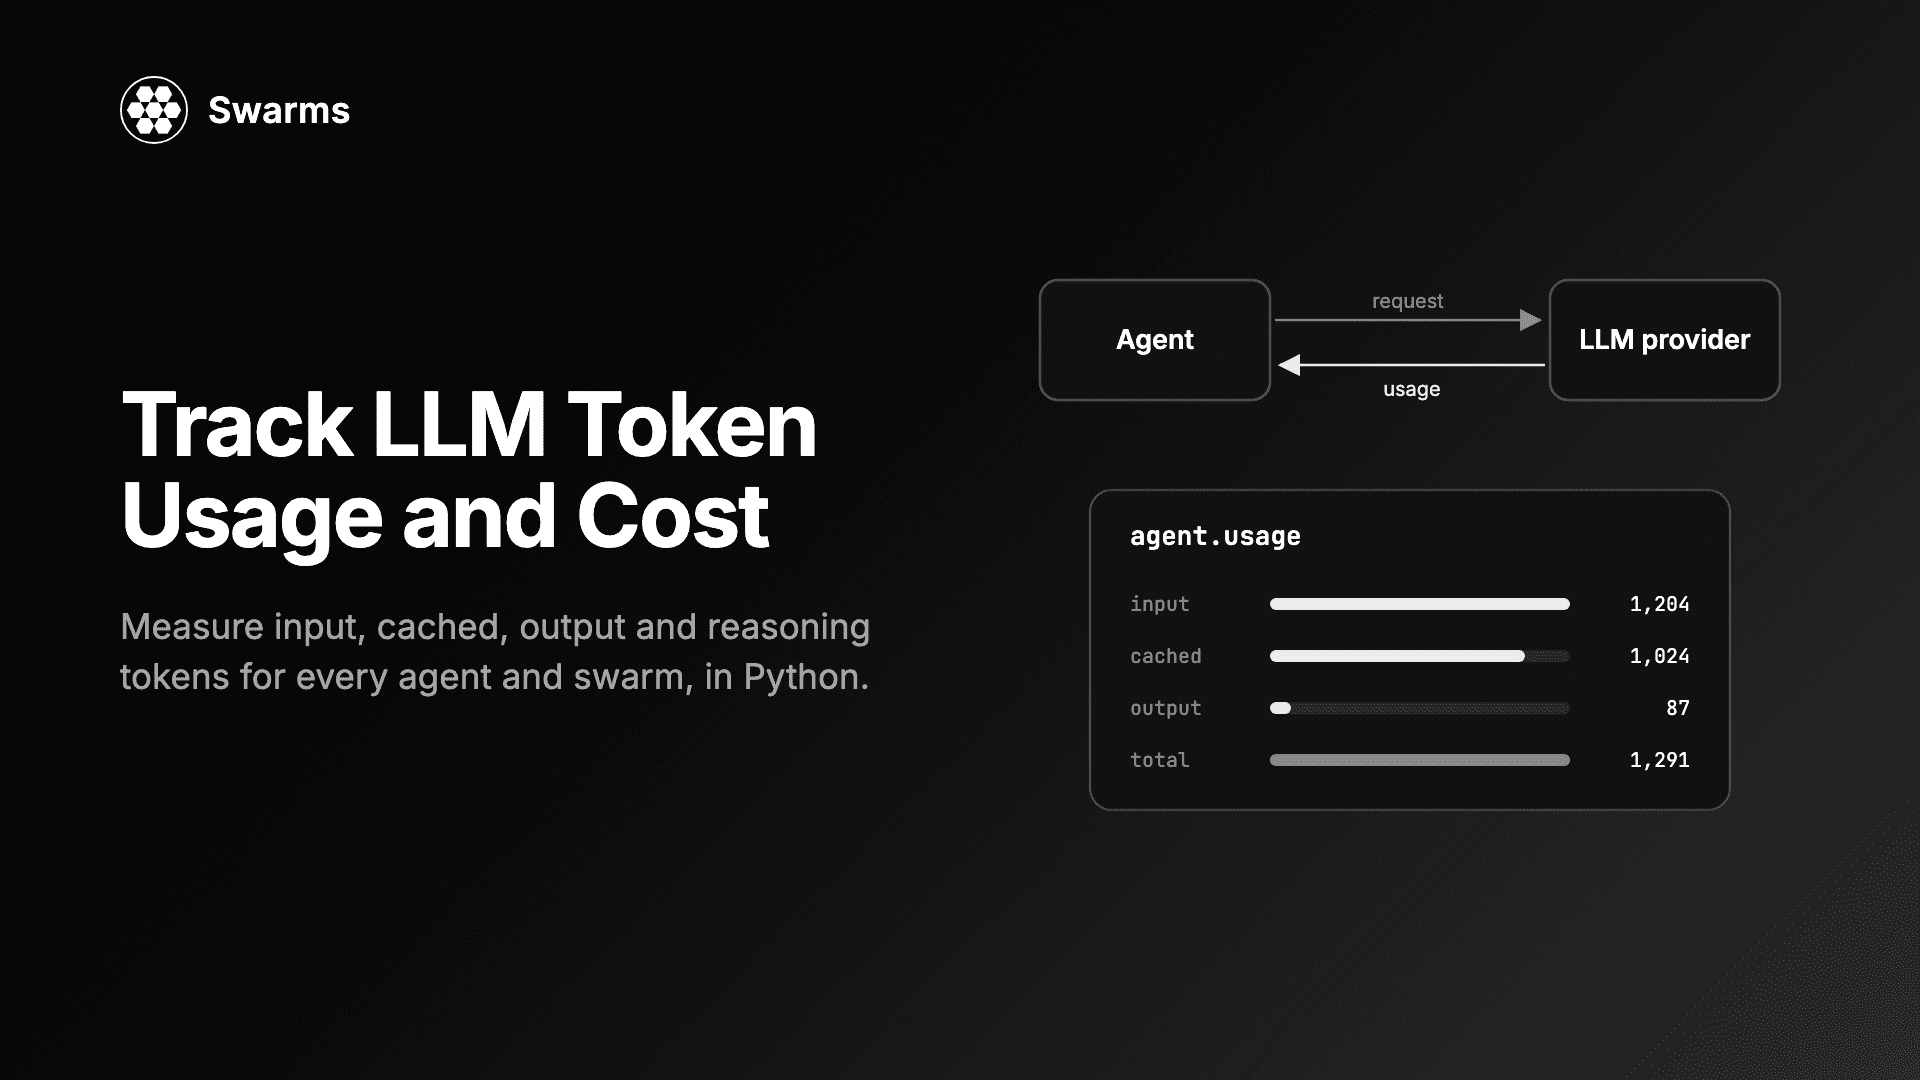
用 Python 追踪每个智能体的 LLM token 用量与成本:输入、输出、缓存与推理 token,单次运行快照,美元成本换算,以及 Swarms 中整个 swarm 的用量合计。